

Alibaba's Qwen3.8-27B Beats Its Own Closed Model Running on a Laptop
Alibaba's new 27B vision-language model runs locally on a laptop at 17GB quantized, with 262k context and coding scores beating closed rivals.
 PRO
- Alibaba released Qwen3.8-27B, a 27B dense vision-language model under Apache 2.0.
- LM Studio GGUF quantization shrinks it to ~17GB, runnable on high-end laptops.
- 262k native context, extensible to 1M via YaRN rope scaling.
- Beats closed Qwen 3.7-Plus on SWE-bench Pro, Terminal Bench, OSWorld and MathVision.
- Multi-Token Prediction gives 72% inference speedup with llama.cpp draft-mtp.
- Default xhigh reasoning wildly overthinks; dial down for practical use.
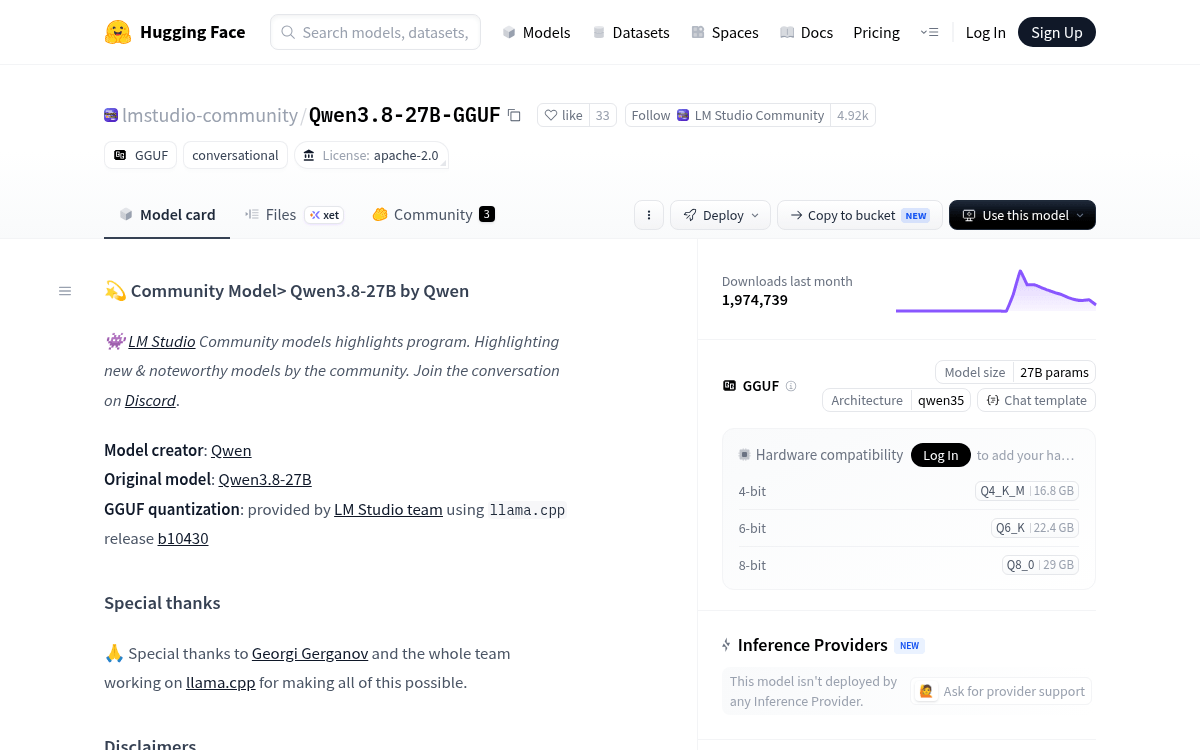
Alibaba's Qwen team just dropped an open-weights model that punches well above its weight class, and the LM Studio community GGUF conversion is what most people are actually running. The underlying model, Qwen3.8-27B, is a 27B-parameter vision-capable LLM from Alibaba's Qwen research lab released under Apache 2.0. The quantized GGUF build shrinks the whole thing down to a 17GB file that runs on a reasonably specced laptop while still handling code, images, tool use, and long-horizon agent loops.
The lmstudio-community repo has already crossed 1.97 million downloads, which gives you a sense of how quickly this landed. The quantization is provided by the LM Studio team using llama.cpp release b10430, so it drops straight into any llama.cpp-compatible runtime.
What actually shipped
Qwen3.8-27B is a dense 27B-parameter causal language model with a native vision encoder, meaning it can read images and video without a bolted-on adapter. Key specs from the model card:
- Context length: 262,144 tokens native, extensible to 1M with YaRN rope scaling
- Architecture: Hybrid stack repeating 3 blocks of Gated DeltaNet linear attention followed by 1 block of Gated Attention, across 64 layers
- Multimodal: Handles images, documents, and hour-scale video natively
- License: Apache 2.0, fully open weights
- Quantized size: Roughly 17GB at Q4_K_M, fitting on a single high-end consumer GPU or unified-memory Mac
Ecosystem builds confirm the footprint: quantized versions run locally on roughly 17GB of RAM or VRAM, and Ollama's build is an 18GB download. A 27B-class dense model typically needs about 56GB of VRAM at BF16, 28GB at FP8, and 14 to 16GB at 4-bit before KV cache overhead.
Benchmarks that force a double-take
This story is for Pro members
You've reached the end of the free preview. Upgrade to AlphaSignal Pro to read the full article - and everything else behind the paywall.
Comments
