

Agenta Quietly Hits 4,000 Stars Replacing LLMOps Chaos With One Open-Source Workspace
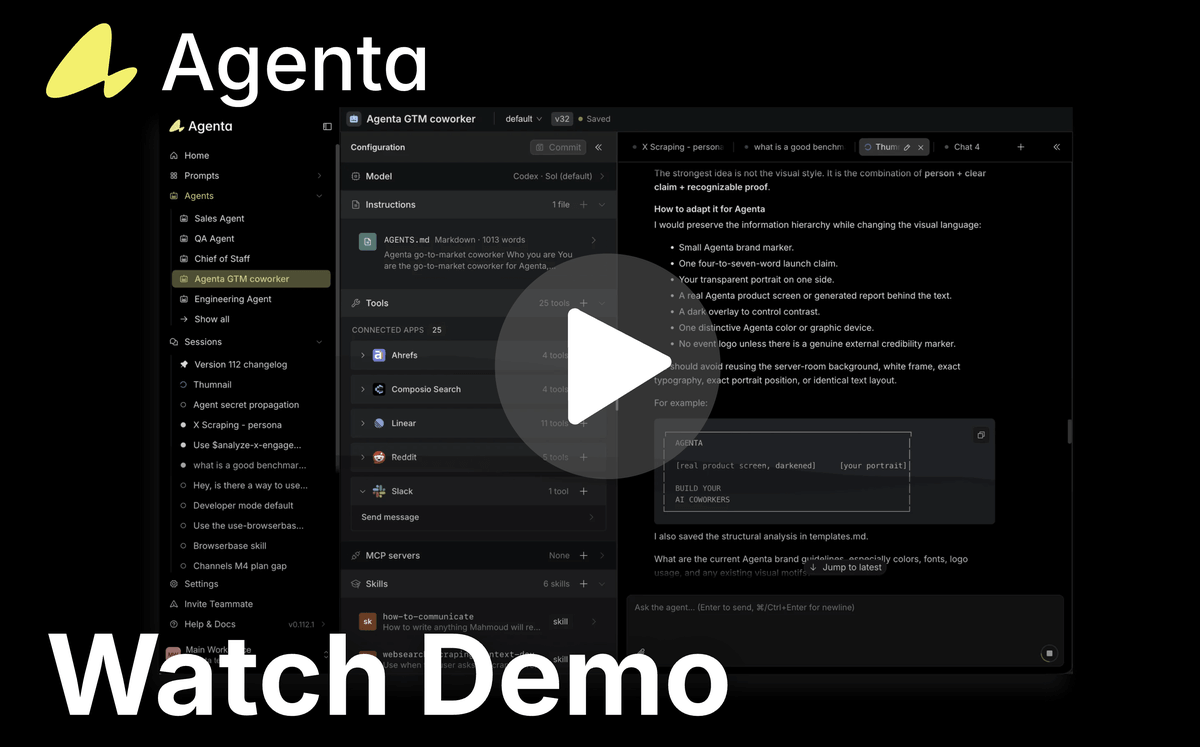
Agenta bundles a prompt playground, versioning, evaluation harness, and OpenTelemetry-based tracing into one open-source LLMOps stack you can self-host.
 PRO
- Agenta is an open-source LLMOps platform covering prompt management, evaluation, and observability in one repo.
- Interactive playground supports 50+ LLM models and side-by-side prompt comparison with full version history.
- Evaluation includes 20+ pre-built evaluators, LLM-as-judge, custom scorers, and human annotation workflows.
- Observability is OpenTelemetry-native and compatible with OpenLLMetry and OpenInference, avoiding proprietary trace lock-in.
- Self-host with a single docker compose command, or use the free cloud tier with 5,000 traces per month.
- Best for teams where product managers or domain experts need to co-edit prompts alongside engineers.
Shipping an LLM app to production usually means duct-taping together a prompt spreadsheet, a Jupyter notebook full of evals, a tracing SaaS, and a Slack thread with your domain experts. Agenta is an open-source project trying to collapse that mess into a single workspace, and it has quietly grown to over 4,000 GitHub stars with a permissive license and a self-hostable Docker setup.
The platform bundles prompt management with version control, systematic evaluation, and production observability for engineering and product teams. Its pitch targets a familiar pain point: teams keep prompts in code where subject matter experts cannot edit them, or they resort to spreadsheets in a brittle handoff process.
What ships in the box
The repo covers three tightly connected surfaces rather than a single feature. Under the hood it runs a polyglot stack, roughly 58% TypeScript for the web app and 40% Python for the SDK and services, with a FastAPI-style backend and a Next.js frontend.
- Prompt playground and management: an interactive UI to compare prompts side by side, with support for over 50 LLM models and custom model integration, plus branching and environments for versioning.
- Evaluation: testsets built from production traces, playground runs, or CSV uploads, scored with 20+ pre-built evaluators, LLM-as-judge, or your own custom code, runnable from the UI or programmatically.
This story is for Pro members
You've reached the end of the free preview. Upgrade to AlphaSignal Pro to read the full article - and everything else behind the paywall.
Comments
