

AEON vLLM Ultimate Fixes NVIDIA DGX Spark's Broken AI Stack in One Pull
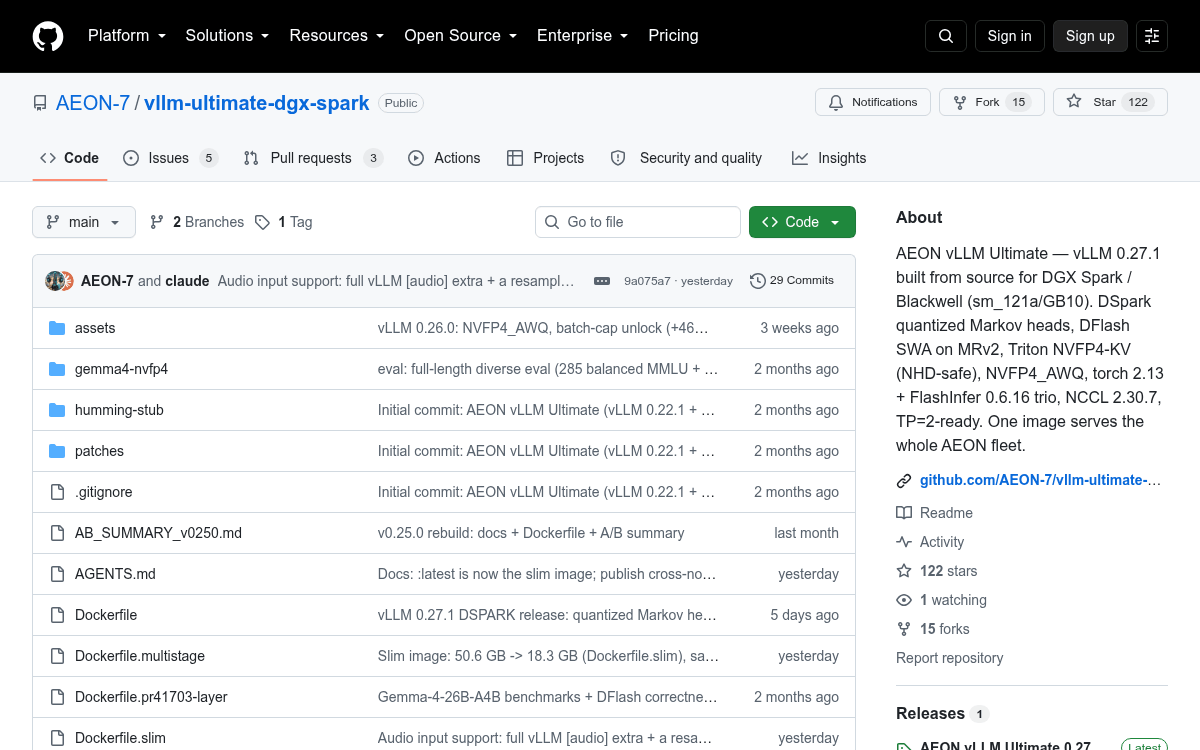
A community-built vLLM container brings NVFP4 KV cache, DFlash speculative decoding, and Blackwell sm_121a runtime patches to DGX Spark serving.

 PRO
- New AEON vLLM Ultimate container packages vLLM 0.22.1 with Blackwell sm_121a runtime patches for DGX Spark GB10.
- Ships NVFP4 KV cache via Triton path (PR #44389), delivering roughly 3× KV capacity on Qwen3.6 models.
- Bundles DFlash and EAGLE3 speculative decoding plus TurboQuant K8V4 4-bit KV compression, wired natively via --speculative-config.
- Benchmarks show MTP-XS body + DFlash drafter + BF16 KV as the Spark winner, +40% single-stream tok/s.
- Math and code hit 44 to 46 tok/s single-stream on GB10, prose about 26 tok/s.
- Docker image at ghcr.io/aeon-7/aeon-vllm-ultimate:latest, Apache-2.0 upstream, free to use.
Getting vLLM to run cleanly on NVIDIA's DGX Spark has been a special kind of pain. The GB10 chip inside Spark reports as compute capability sm_121a, which upstream kernels do not fully target yet, and several recent inference tricks like NVFP4 KV caches and non-causal speculative decoders were built assuming SM100 or SM90 hardware. A new open-source container called AEON vLLM Ultimate tries to fix that whole stack in one shot.
The project ships as a Docker image containing vLLM 0.22.1 with PR #44389 cherry-picked, plus TurboQuant, DFlash speculative decoding, and a handful of runtime patches specifically for the sm_121a target. It is built for TORCH_CUDA_ARCH_LIST="12.1a" and also runs on RTX 5090, RTX 5080, and RTX PRO 6000 Blackwell (sm_120) via vLLM's family matcher.
What's actually in the box
The image pulls from ghcr.io/aeon-7/aeon-vllm-ultimate:latest and bundles several moving parts that are otherwise a compile-and-patch ordeal on Spark:
- NVFP4 KV cache via a Triton software path that packs the KV cache as E2M1 FP4 values with E4M3 block scales, activated per-serve with --kv-cache-dtype nvfp4, and works on any sm_120 / sm_121 / sm_100 / sm_90 GPU.
- TurboQuant K8V4, a 4-bit KV compression layer, with a fork that caches a small constant array per-device at module load instead of reallocating per call, avoiding a CUDA-graph capture crash that otherwise forces --enforce-eager and costs about 30% throughput.
This story is for Pro members
You've reached the end of the free preview. Upgrade to AlphaSignal Pro to read the full article - and everything else behind the paywall.
Comments
