

A College Student Built ATLAS to Beat Frontier Coding Models Locally
ATLAS is a fully local, open-source coding agent that wraps a frozen 14B model in a multi-phase pipeline to hit 74.6% on LiveCodeBench — no API keys, no cloud, no fine-tuning required.
 PRO
- ATLAS is a fully local, open-source coding agent that achieves 74.6% on LiveCodeBench using a frozen 14B model on a single consumer GPU.
- It works by wrapping a small model in a multi-phase pipeline: structured planning, diverse candidate generation, energy-based scoring, sandboxed testing, and iterative repair.
- The Geometric Lens — a small MLP trained on model embeddings — predicts which candidate is correct before running any tests, cutting down expensive sandbox execution.
- No API keys, no cloud, no fine-tuning: your code never leaves your machine; the only cost is electricity.
- Limitations include slow generation (~51 tok/s with grammar constraints), a 16GB+ VRAM requirement, and benchmark scores measured under a more favorable methodology than single-shot frontier comparisons.
- The latest release, V3.1.3 "Maia", replaces Redis with SQLite, adds staged rollback, signed manifests, and session resume for production stability.
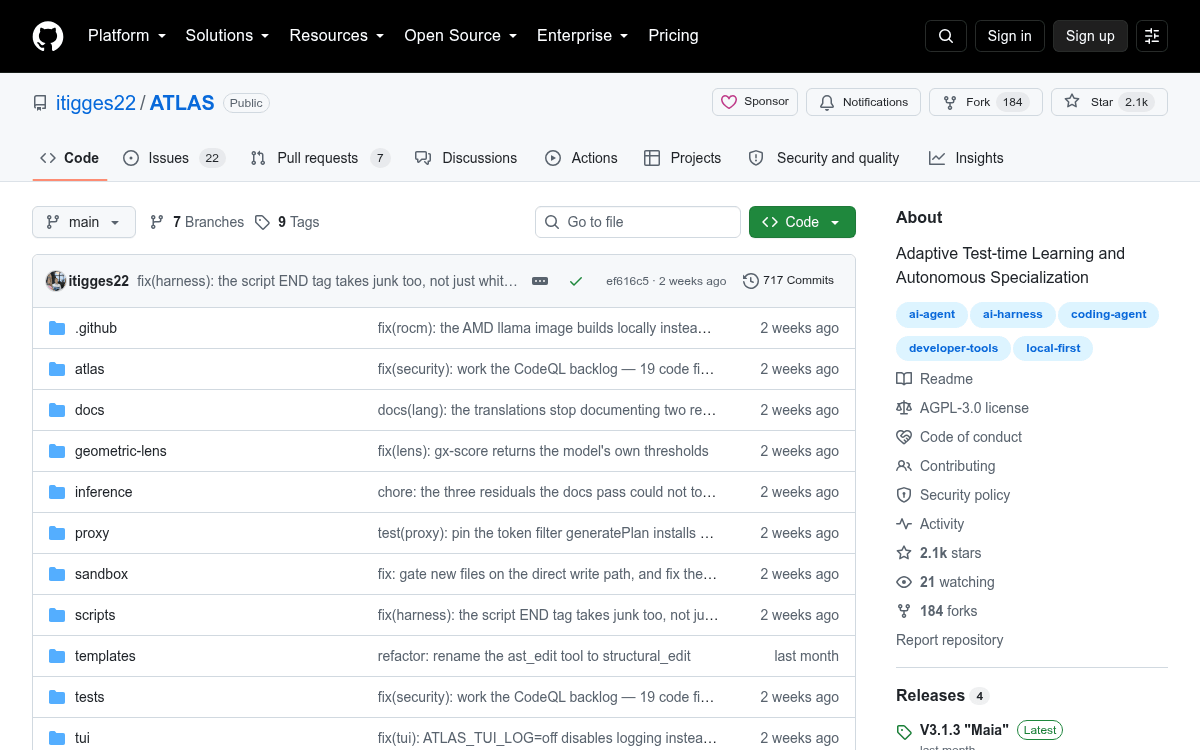
ATLAS (Adaptive Test-time Learning and Autonomous Specialization) is a self-hosted coding agent built by a single college student on a single consumer GPU. The premise is simple but powerful: instead of relying on a bigger model or expensive API calls, ATLAS wraps a compact, frozen 14B model in a smart pipeline that plans, generates multiple candidates, scores them, tests them in a sandbox, and repairs failures , all locally, with no data leaving your machine.
ATLAS achieves 74.6% on LiveCodeBench using a frozen 14B quantized model (Qwen3-14B-Q4_K_M) on a single consumer GPU (RTX 5060 Ti 16GB). That's a result that puts it in the same conversation as hosted frontier models , and it costs nothing but electricity per query.
The Problem It Solves
The standard coding agent workflow is a single-shot gamble: you send a prompt, you get one generation, and you hope it works. When the model is small, that gamble fails often. ATLAS is a local coding agent that brings frontier-style reasoning and verification to compact open models, putting more intelligence in the system around the model , planning, candidate generation, quality scoring, sandboxed testing, and repair , so smaller models can tackle real software work entirely on your own hardware, without a hosted API or per-token fees.
This matters most if you care about privacy, cost control, or just don't want to depend on a third-party service that can change its terms, rate-limit you, or disappear. ATLAS does not intentionally upload your repository or prompts to a hosted model or ATLAS-operated service.
How the Pipeline Actually Works
The magic is in the orchestration layer, not the model. ATLAS runs a multi-phase process called the V3 Pipeline every time you make a request:
- PlanSearch: Before writing any code, ATLAS generates a structured, constraint-driven plan. It figures out what the problem requires before attempting a solution.
- DivSampling: Multiple candidate solutions are generated with varied temperatures and strategies , not just one attempt, but a diverse pool.
- Budget Forcing: Thinking-token budgets are allocated per phase, so harder problems get more reasoning compute.
This story is for Pro members
You've reached the end of the free preview. Upgrade to AlphaSignal Pro to read the full article - and everything else behind the paywall.
Comments
