
SuperGemma4 Hits 98K Downloads Running Uncensored on a MacBook
A community GGUF quant of Google's Gemma 4 26B MoE strips safety guardrails and hits 89 tokens per second on Apple Silicon.
 Pro
Takeaways
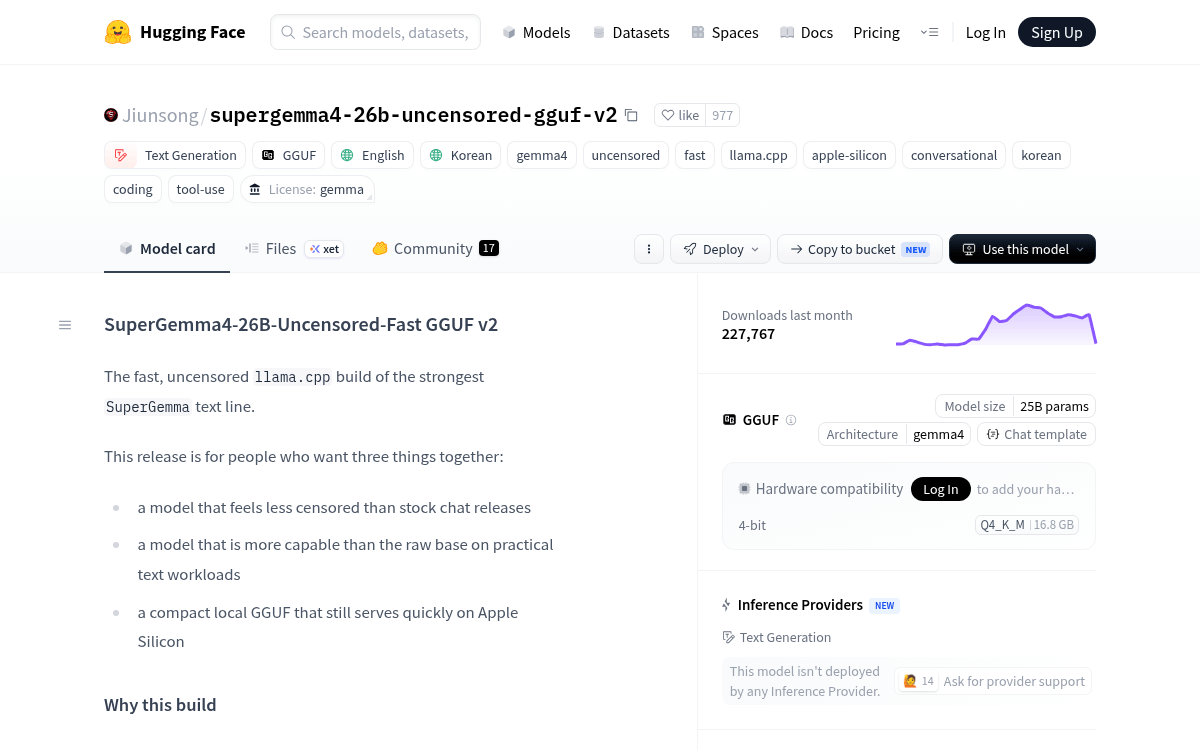
- Jiunsong released SuperGemma4-26B-Uncensored GGUF v2, an abliterated Q4_K_M quant of Gemma 4 26B A4B.
- Base model Gemma 4 26B A4B IT is a MoE with 25.2B total and 3.8B active parameters.
- Hits 89.4 tok/s generation and 222 tok/s prompt processing on an Apple M4 Max via llama.cpp.
- Single 16.8 GB GGUF file with neutral chat template to fix Gemma 4's coding-mode drift on general prompts.
- Supports English and Korean, runs in Ollama, LM Studio, Jan, vLLM, and llama.cpp out of the box.
- Over 98,000 downloads on Hugging Face; ships under Google's Gemma license, not Apache.
A developer going by Jiunsong has published SuperGemma4-26B-Uncensored Fast GGUF v2, a repackaged and abliterated build of Google's newest Mixture-of-Experts model tuned to run comfortably on a MacBook. It has already crossed 98,000 downloads on Hugging Face, making it one of the more popular community quants of the Gemma 4 family so far.
The base is google/gemma-4-26B-A4B-it, the instruction-tuned MoE in Google DeepMind's latest lineup. Despite 25.2B total parameters, only 3.8B activate per token during inference, delivering near-31B quality at a fraction of the compute cost. That efficiency profile is what makes a 26B model realistic to run locally in the first place.
What the community build actually changes
This release is a repackaging of a stronger derivative line plus a chat-template fix, exported to GGUF Q4_K_M for llama.cpp, rather than a from-scratch fine-tune. The author frames it around three goals: a model that feels less censored than stock chat releases, one that is more capable than the raw base on practical text workloads, and a compact local GGUF that still serves quickly on Apple Silicon.