
Red Hat Shrinks Google's Gemma 4 31B in Half With Near-Perfect Accuracy
Red Hat AI shipped a block-wise FP8 quantization of Gemma 4 31B that halves memory while matching or beating the original on most benchmarks.
 Pro
Takeaways
- Red Hat AI released an FP8-block quantization of Gemma 4 31B, halving memory with near-identical accuracy.
- Weights use 128x128 block FP8 scaling; activations use dynamic per-group quantization at group size 128.
- Vision tower, embeddings, and output head are left in original precision to preserve multimodal quality.
- Recovery is 100% or better on MMLU-Pro, GSM8K, GPQA Diamond, and LiveCodeBench v6.
- Weakness: BFCLv4 agentic tool use drops to 85.9% recovery, worth testing for agent workloads.
- Built data-free with LLM Compressor and deployable via a single
vllm servecommand.
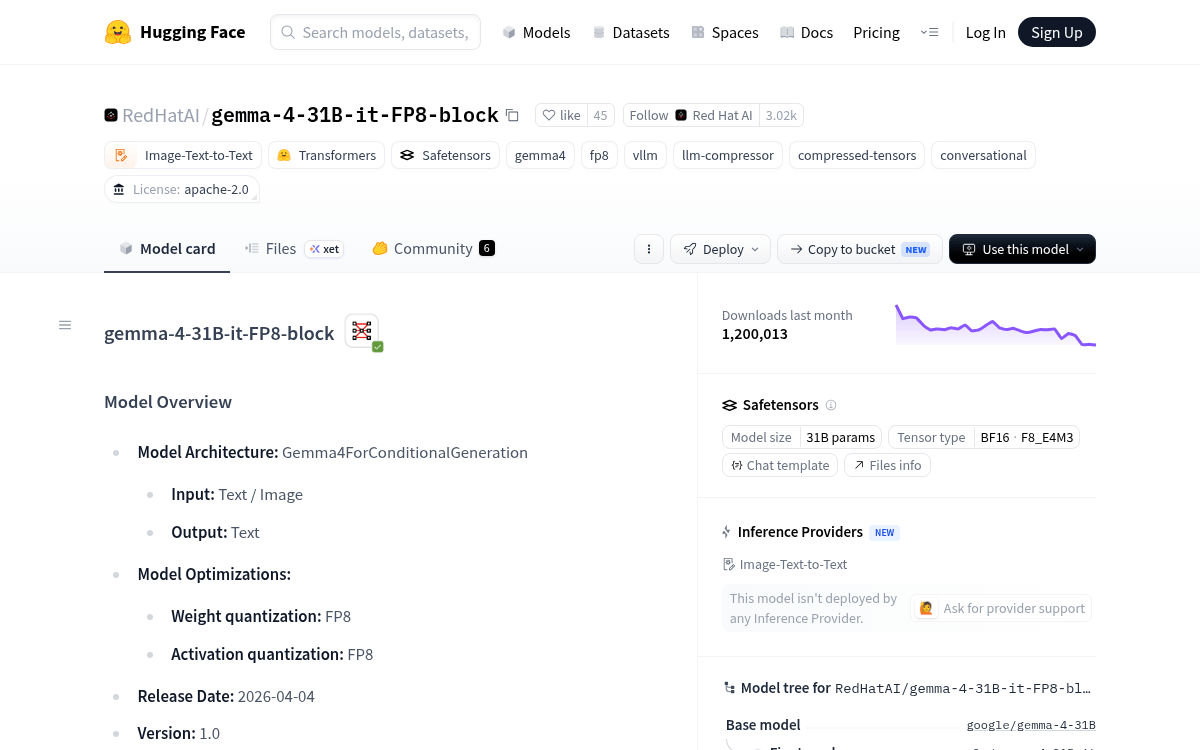
Red Hat AI has published an FP8-quantized checkpoint of Google's Gemma 4 31B instruct model that cuts memory and disk footprint roughly in half while keeping accuracy essentially untouched on almost every benchmark. The release drops directly into vLLM and SGLang, and it inherits the full Gemma 4 multimodal stack including image input, thinking mode, and tool calls.
What was actually shipped
The checkpoint is a post-training quantization of google/gemma-4-31B-it. Weights and activations were converted from 16 bits per parameter to 8, cutting disk size and GPU memory requirements by roughly half.
The interesting part is how the quantization is arranged. Weights use block-wise FP8 scaling in 128x128 blocks, and activations are quantized dynamically per group with a group size of 128. Only the weights and activations of the linear operators within transformer blocks go through LLM Compressor. The vision tower, embedding, and output head layers stay in their original precision, which preserves multimodal quality and stops logit drift.
It ships under Apache 2.0 and is free to pull from Hugging Face. Serving it is a one-liner:
pip install vllm
vllm serve RedHatAI/gemma-4-31B-it-FP8-block \
  --tensor-parallel-size 2 \
  --max-model-len 32768 \
  --enable-auto-tool-choice \
  --reasoning-parser gemma4 \
  --tool-call-parser gemma4