
RadixArk's Qwen3.8-27B Squeezes a 27B Model onto One Consumer GPU at 97% Accuracy
RadixArk shipped an NVFP4 W4A4 quantization of Qwen3.8-27B that runs on a single RTX 5090 while keeping GSM8K accuracy above 97%.
Takeaways
- RadixArk released Qwen3.8-27B-NVFP4, a 4-bit quantization of Qwen3.8-27B for Blackwell GPUs.
- Uses a mixed recipe: NVFP4 W4A4 for MLPs, FP8 attention, BF16 for MTP and vision tensors.
- Scores 97.27% on GSM8K and 73.81% on Terminal-Bench 2.1 with SGLang on GB300.
- Runs on a single RTX 5090 via vLLM with full 256K context.
- A BF16-lm_head variant ships alongside it for stricter accuracy needs.
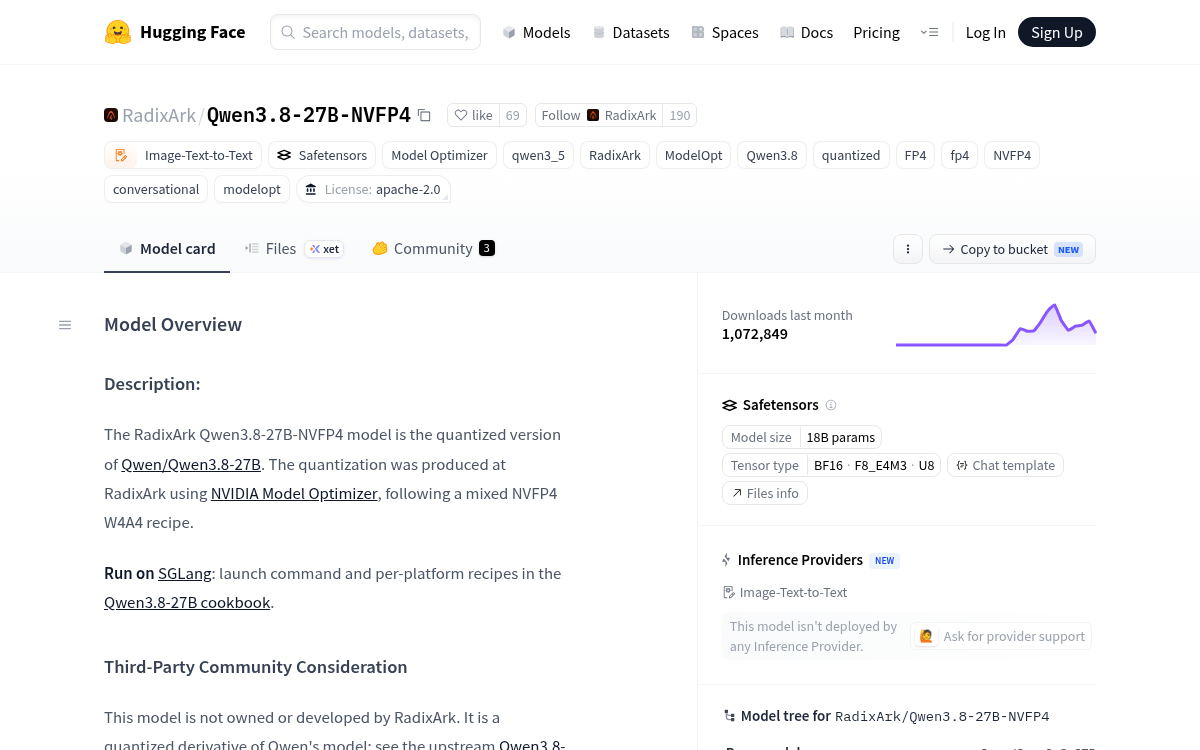
- Over 1M downloads on Hugging Face under Apache 2.0, keeping multimodal input intact.
A new 4-bit checkpoint of Qwen3.8-27B has quietly become one of the most downloaded models on Hugging Face, crossing a million pulls in a few weeks. RadixArk's Qwen3.8-27B-NVFP4 is a post-training quantization of the base Qwen model that shrinks the checkpoint to roughly 22 GB, small enough to fit on a single consumer Blackwell GPU, while holding onto near-BF16 accuracy on reasoning and coding benchmarks.
RadixArk produced the quantization with NVIDIA Model Optimizer, following a mixed NVFP4 W4A4 recipe. NVFP4 is NVIDIA's 4-bit floating point format for the Blackwell generation, where weights and activations are packed into 4 bits (W4A4) with small per-group scale factors rather than a single per-tensor scale. That yields the memory footprint of INT4 without the accuracy collapse that usually follows when you quantize activations.
A recipe that spares the right layers
What did and did not get quantized turns out to be the interesting part. The MLP gate_proj, up_proj, and down_proj layers and lm_head use dynamic NVFP4 W4A4 quantization with group size 16. Attention weights use FP8, while MTP and vision tensors retain the source BF16 precision. The bulky feed-forward matrices get the aggressive 4-bit treatment, attention stays at 8-bit for stability, and the multi-token prediction heads plus the vision tower keep full BF16 precision so multimodal quality does not degrade.