
Qwen3.6 Fork Hits 1M Downloads After Cracking the Uncensoring Tradeoff
A community-released uncensored fork of Qwen3.6-35B-A3B uses a single-direction weight edit to hit 0% refusal without wrecking the base model's capabilities.
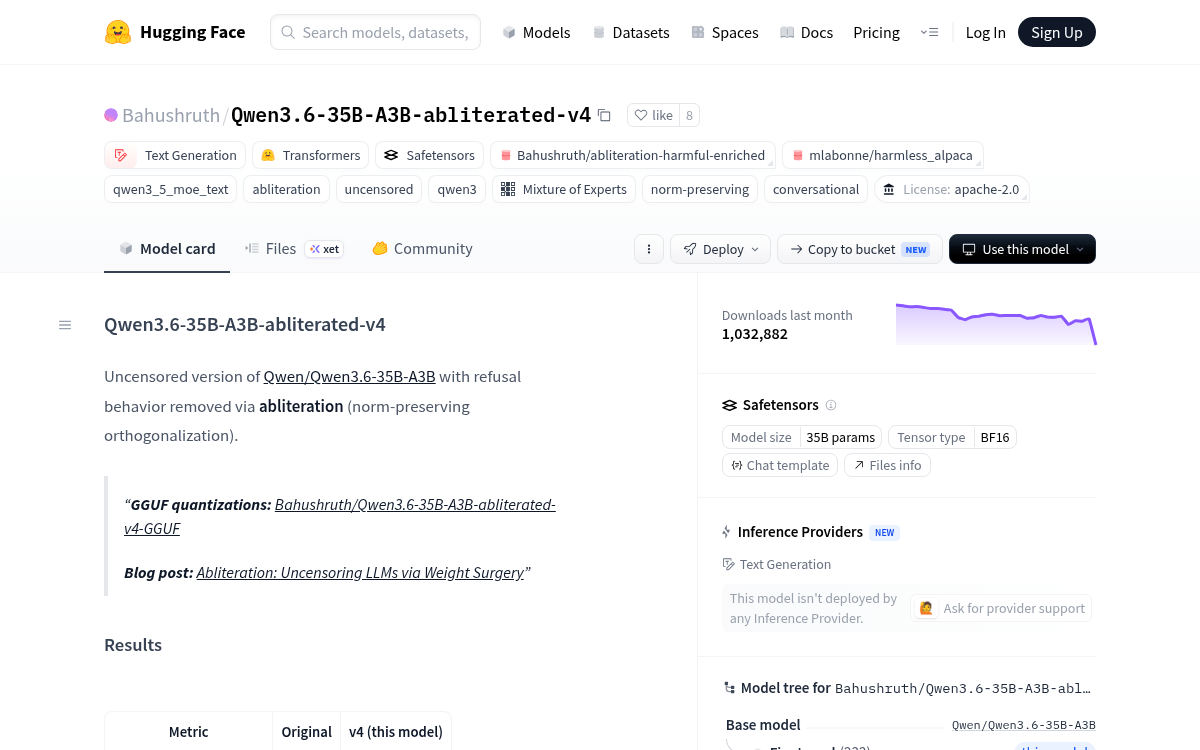
Takeaways
- Uncensored fork of Qwen3.6-35B-A3B hits 0% refusal via weight-surgery abliteration.
- Over 1 million downloads on Hugging Face despite being a solo community release.
- Uses norm-preserving orthogonalization to keep capabilities intact after removing the refusal direction.
- A single direction from 7,356 diverse prompts beat prior 7 or 10 direction attempts.
- MoE base has 35B total, 3B active parameters, 256 experts per layer, Apache 2.0 license.
- GGUF quantizations ship for llama.cpp, Ollama, and LM Studio.
A new abliterated fork of Qwen3.6-35B-A3B has quietly become one of the most downloaded models on Hugging Face, racking up over a million downloads. Qwen3.6-35B-A3B-abliterated-v4 strips refusal behavior from Alibaba's mixture-of-experts model using a weight-editing technique that, unlike previous attempts, keeps the underlying capabilities intact.
Another uncensored Qwen is not the story. The author appears to have solved the classic tradeoff where removing refusals also lobotomizes the model. The results table on the model card claims a 0% refusal rate on harmful prompts (down from ~98% in the base) with 0% false refusals on harmless ones, and no visible capability degradation on standard benchmarks.
What abliteration actually does
Abliteration is a weight-surgery technique popularized by Maxime Labonne. It uncensors any LLM without retraining by removing the built-in refusal mechanism, allowing the model to respond to all types of prompts. The core idea comes from mechanistic interpretability work by Arditi et al., who showed that refusal behavior is mediated by a specific direction in the model's residual stream.
The recipe, in short:
- Run a batch of harmful and harmless prompts through the model and capture activations at the last token.
- Compute the mean difference between the two sets to get a candidate refusal direction per layer.