
Mistral AI Quietly Upgrades Mistral-7B-v0.1 Serving Stack Without Changing Weights
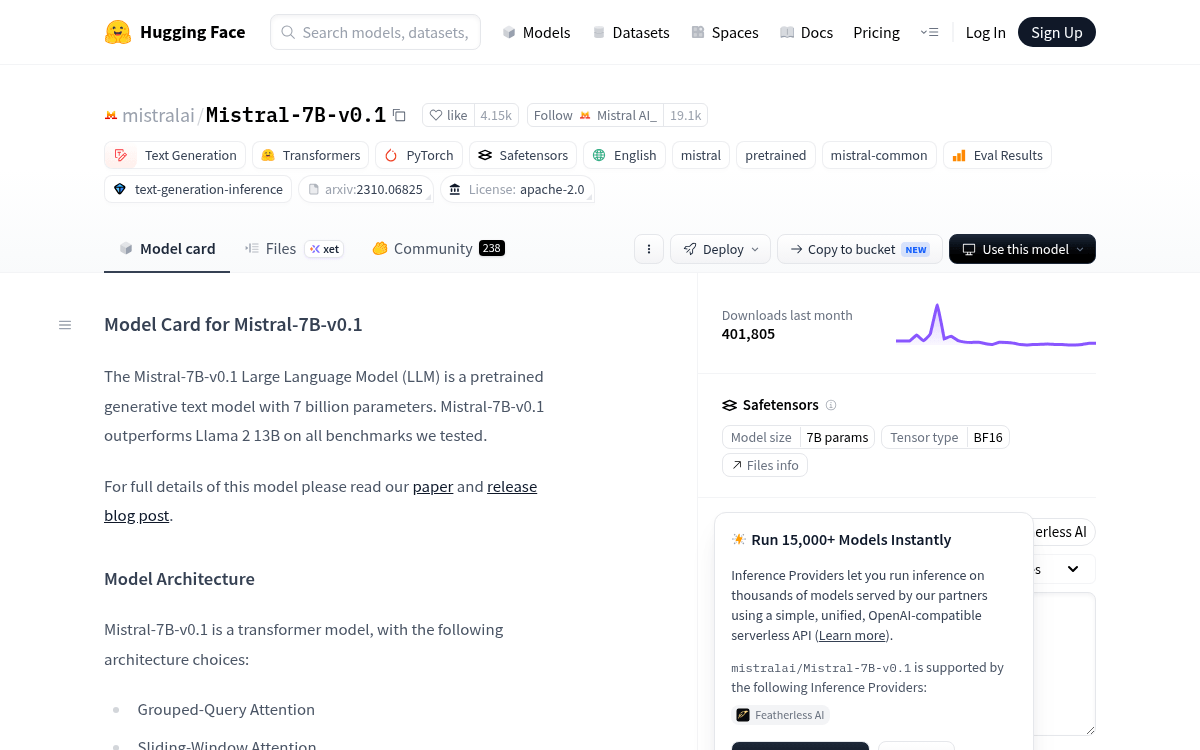
Mistral AI refreshed the Mistral-7B-v0.1 repository with mistral-common tokenizer support and one-command deployment recipes for vLLM, SGLang, and Docker Model Runner.
Takeaways
- Mistral AI updated the Mistral-7B-v0.1 repo with mistral-common tokenizer integration.
- Model card now includes one-command vLLM, SGLang, and Docker Model Runner launchers.
--tokenizer_mode mistralpath unifies serving across Mistral's full model lineup.- Tool-call parser and auto tool choice are enabled by default in the vLLM recipe.
- Base weights and Apache-2.0 license unchanged; architecture still uses GQA and sliding-window attention.
- Ecosystem still huge: 2,457 adapters, 947 finetunes, 193 quantizations depend on this base.
Mistral AI has quietly refreshed the repository for its original 7B base model, wiring Mistral-7B-v0.1 into the same tokenizer and serving stack it uses for newer releases. The update adds a mistral-common tag to the model, along with copy-paste deployment recipes for vLLM, SGLang, and Docker Model Runner directly on the model card.
The weights themselves are unchanged. Mistral-7B-v0.1 remains a pretrained generative text model with 7 billion parameters that outperforms Llama 2 13B on every benchmark Mistral tested. What changes is how you are expected to load, tokenize, and serve it in production.
What mistral-common actually does
mistral-common is Mistral's official pre-processing library. It open-sources the tokenizers, validation, and normalization code for Mistral models, covering requests, messages, tool calls, and responses. The tokenizers are versioned to guarantee backward compatibility for released models.