
LocalAI's Qwen3.6 Runs Claude-Style Reasoning on One GPU Without Sacrificing Quality
A LocalAI quantization bundles the multi-token prediction head into a single GGUF, giving Claude-distilled Qwen3.6 self-speculative decoding without a draft model.
Takeaways
- LocalAI's APEX-MTP GGUF ships Qwen3.6-35B-A3B fine-tuned on Claude Opus 4.6 reasoning traces.
- Single file bundles the MTP draft head for self-speculative decoding, no second model required.
- Enable it in recent llama.cpp with the
--draft-mtpflag on llama-server. - APEX quantization compresses routed experts hardest while keeping shared experts and edge layers at higher precision.
- 35B total parameters, 3B active per token, 256 routed experts, Apache 2.0 license, 40 trunk plus 1 MTP layer.
- MoE speedup from MTP is real but smaller than on dense models since baseline decoding is already cheap.
Running a 35B reasoning model on a single GPU has usually meant picking your poison: quantize aggressively and lose quality, or accept slow token generation. A new release from the LocalAI team sidesteps that trade with a single GGUF file that ships its own speculative decoder inside.
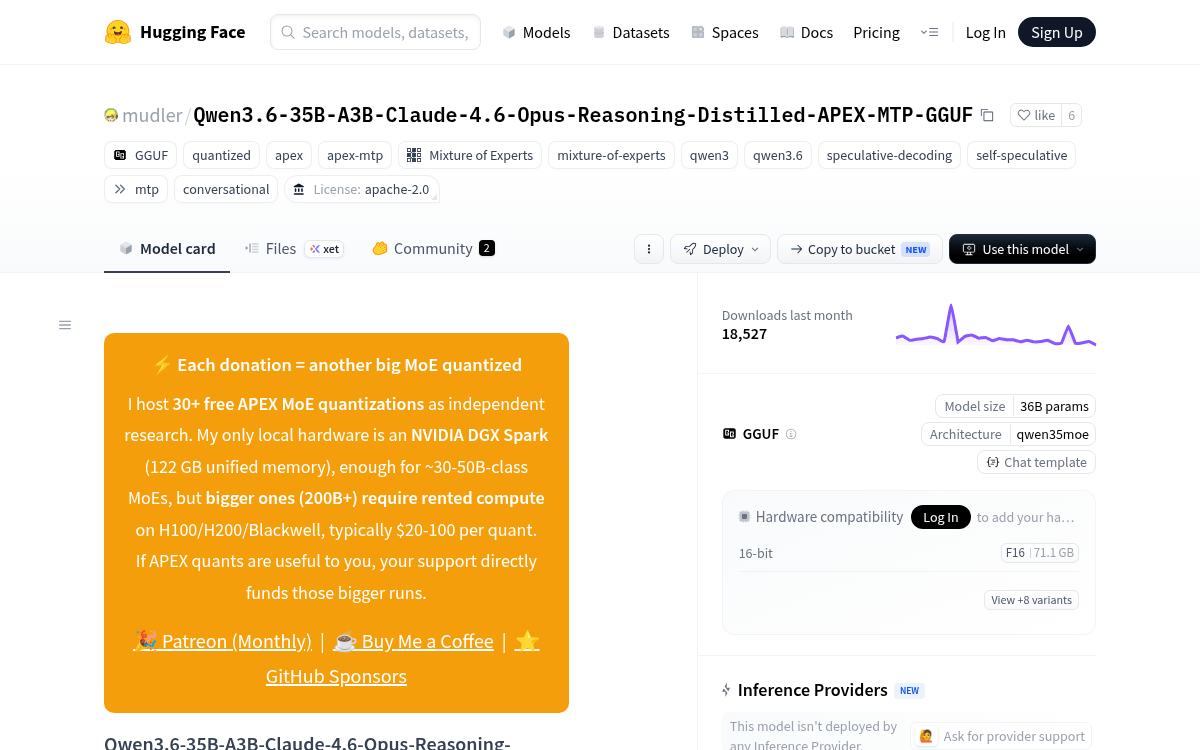
The model is Qwen3.6-35B-A3B-Claude-4.6-Opus-Reasoning-Distilled-APEX-MTP-GGUF, a quantized build of hesamation's Claude-distilled Qwen. The base is a reasoning SFT fine-tune of Qwen3.6-35B-A3B. The training recipe samples and normalizes reasoning conversations from three datasets, then renders them with the qwen3-thinking chat template and response-only SFT masking, aimed at reasoning-heavy workflows such as coding assistance, planning, math-style reasoning, and structured analytical responses. It ships under Apache 2.0 and is free to download.
Why the MTP head changes the math
The headline trick is self-speculative decoding through a bundled multi-token prediction (MTP) head. In classic speculative decoding, you run a small draft model alongside the main one, and the large model only has to verify the draft's guesses. That means shipping two sets of weights and juggling both at inference time.
This release bundles the MTP head alongside the trunk in a single file, courtesy of llama.cpp PR #22673. With a recent llama.cpp (commit 255582687 or later), you can enable self-speculative decoding from just this one file by passing