
Krea AI Ships Krea 2, an Open 12B Image Model Built for Style Control
Krea released a 12B diffusion transformer trained from scratch with open weights, focusing on aesthetic diversity and reference-driven style control over raw benchmark scores.
Takeaways
- Krea 2 is a 12B parameter diffusion transformer released with open weights on Hugging Face
- Two paired checkpoints ship: RAW (52-step base for LoRA training) and Turbo (8-step distilled for fast inference)
- Native ComfyUI support plus bf16, fp8, int8, and community GGUF quantizations down to 3 GB
- Style reference system supports up to 10 images with adjustable weights, including negative style weighting
- Trained via LLM-style pipeline: pretrain, midtrain, SFT, preference optimization with custom STPO, and multi-reward GRPO
- Weakness: struggles with legible in-scene text, UI layouts, and pixel-perfect branding
Krea AI has shipped its first foundation image model as open weights, and the release is worth attention beyond the usual model-of-the-week churn. Krea 2 is a from-scratch 12B parameter diffusion transformer built to prioritize aesthetic range and style controllability over raw benchmark scores, and Comfy-Org has already repackaged the weights for direct use in ComfyUI.
Most image models have quietly converged on a narrow default look. As the field has optimized for reliability, systems have drifted toward a small set of house aesthetics, which weakens them as engines for creative exploration where users need to search across styles, moods, and compositions rather than accept a single polished default. Krea 2 tries to reopen that search space.
What actually shipped
The release includes two open checkpoints designed to be used as a pair. Krea 2 RAW is the base model with full-step sampling at 52 steps, undistilled and highly malleable, ideal for fine-tuning and LoRA training. Krea 2 Turbo is an 8-step distilled checkpoint for fast, high-quality generation, and LoRAs trained on RAW apply seamlessly to Turbo. That workflow decouples training cost from inference cost cleanly: train once on RAW, ship on Turbo.
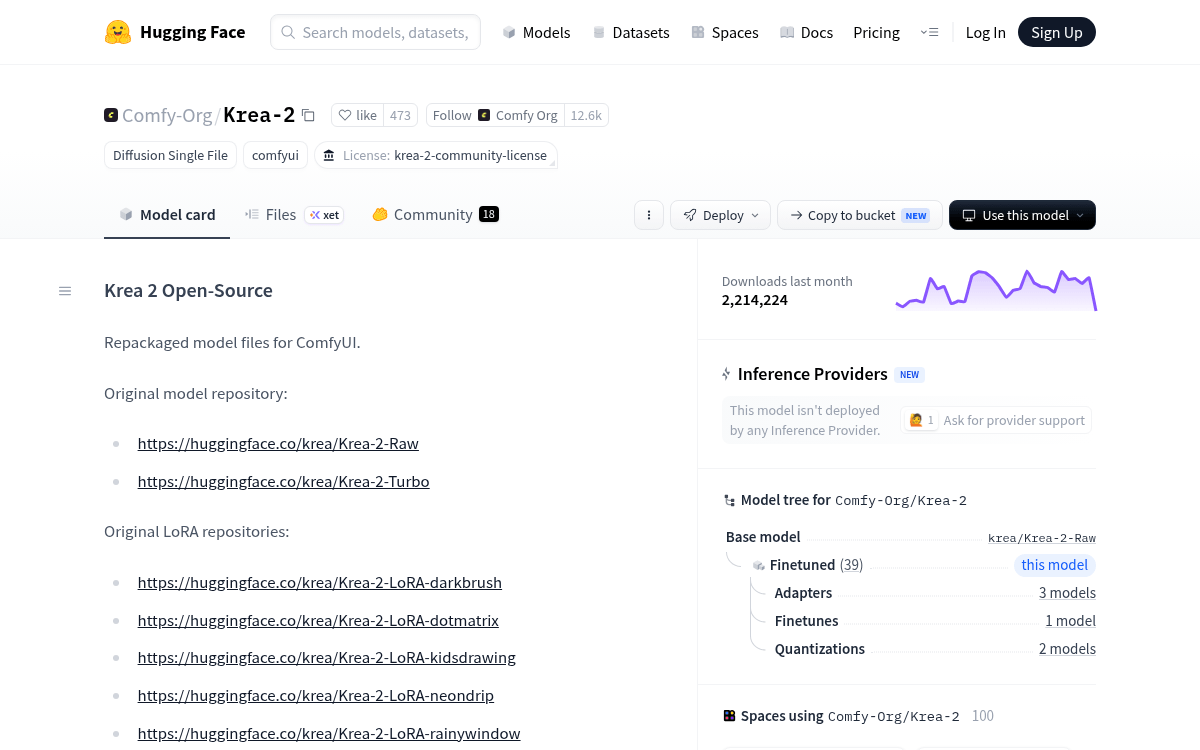
Under the hood, Krea 2 is a 12-billion parameter Diffusion Transformer with a novel architecture featuring layerwise and refiner text-fusion blocks. It is not derived from Flux or any prior open-weight architecture. The Comfy-Org repo ships multiple quantizations so you can pick your VRAM budget, including bf16 (26.3 GB), fp8 scaled (13.1 GB), and int8 convrot (13.5 GB) variants. Community GGUF conversions push the model down further, from Q3_K_S at roughly 3 GB up through Q8_0 at around 13.7 GB, which brings it into reach for consumer GPUs.
Getting it running
ComfyUI is the fastest path in. Recent versions have native support, and the workflow is straightforward: