
IBM's Granite 4.1 8B Beats Its Own 32B Model on Key Tasks
IBM's new 8B dense model matches its previous 32B mixture-of-experts predecessor, ships under Apache 2.0 with a 131K context window and strong tool calling.
 Pro
Takeaways
- IBM released Granite 4.1 8B, a dense decoder-only instruct model with 131K context under Apache 2.0.
- The 8B model matches or beats the previous Granite 4.0 32B mixture-of-experts on most benchmarks.
- Trained on ~15T tokens across five phases, then SFT on 4.1M curated samples plus four-stage RL.
- Strong on instruction following (IFEval 87), math (GSM8K 92.5), code (HumanEval 87.2) and tool calling.
- Weak on frontier reasoning: GPQA 41.96 and SimpleQA 4.82, by design, no chain-of-thought.
- API pricing around $0.05/$0.10 per million tokens; runs on vLLM, SGLang, Ollama, llama.cpp.
IBM has released Granite 4.1 8B, the mid-tier entry in a new family of dense, decoder-only language models aimed at enterprise workloads. The headline claim is unusual for a model this size: the 8B instruct model consistently matches or outperforms the Granite 4.0 32B mixture-of-experts model, using roughly a quarter of the parameters with a simpler architecture. That result is worth unpacking, because it changes what a well-trained 8B can plausibly do.
What just shipped
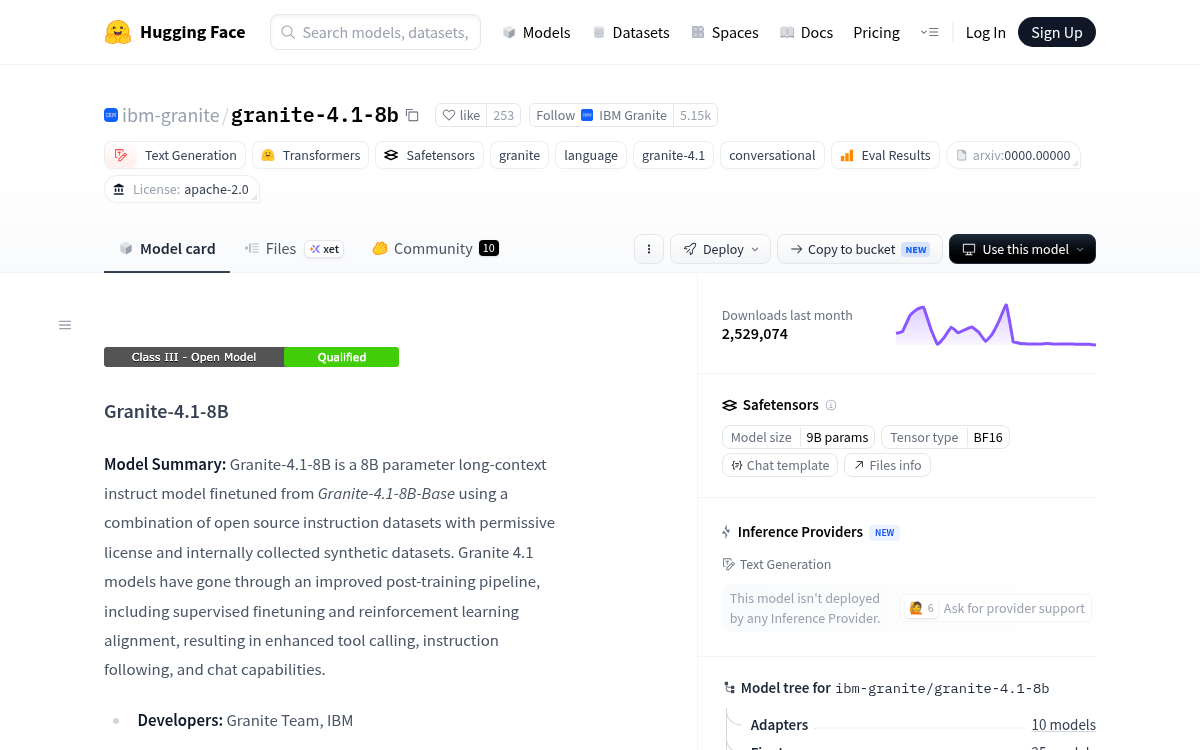
Granite 4.1 comes in three sizes (3B, 8B, and 30B parameters) all under Apache 2.0, with context windows up to 512,000 tokens and trained on approximately 15 trillion tokens. The 8B variant on Hugging Face exposes a 131K context and ships as both base and instruct checkpoints, plus FP8 quantized variants for vLLM.
The model card describes an 8B long-context instruct model finetuned from Granite-4.1-8B-Base using open source instruction datasets and internally collected synthetic data, with an improved post-training pipeline that combines supervised finetuning and reinforcement learning alignment. IBM credits that pipeline with sharper tool calling, instruction following, and chat behavior. Twelve languages are officially supported: English, German, Spanish, French, Japanese, Portuguese, Arabic, Czech, Italian, Korean, Dutch, and Chinese.
Getting it running
The weights are free under Apache 2.0, so self-hosting is the default path. For hosted access, Granite 4.1 8B costs $0.05 per 1M input tokens and $0.10 per 1M output tokens, based on the median across providers, putting it at the cheap end of the 8B API market. Throughput sits at roughly 114.8 tokens per second, above the median for open-weight non-reasoning models of similar size.