
Huihui-Qwen3.6 Ships Uncensored 27B at 110 Tokens per Second on One GPU
A community-modified Qwen3.6-27B ships with refusals surgically removed, AWQ 4-bit quantization, and native multi-token prediction hitting 110+ tokens per second.
Takeaways
- Uncensored Qwen3.6-27B variant ships with AWQ 4-bit weights and native MTP speculative decoding.
- Hits 110+ tokens per second on a single A800 80GB via vLLM 0.21.0 with fp8 KV cache.
- Uses abliteration to project out the refusal direction rather than retraining.
- Keeps Qwen3.6's image-text-to-text multimodal input path intact for VLM workloads.
- Serves through vLLM, SGLang, Docker Model Runner, or plain Transformers under Apache 2.0.
- Author warns safety filtering is minimal, recommending research or controlled use only.
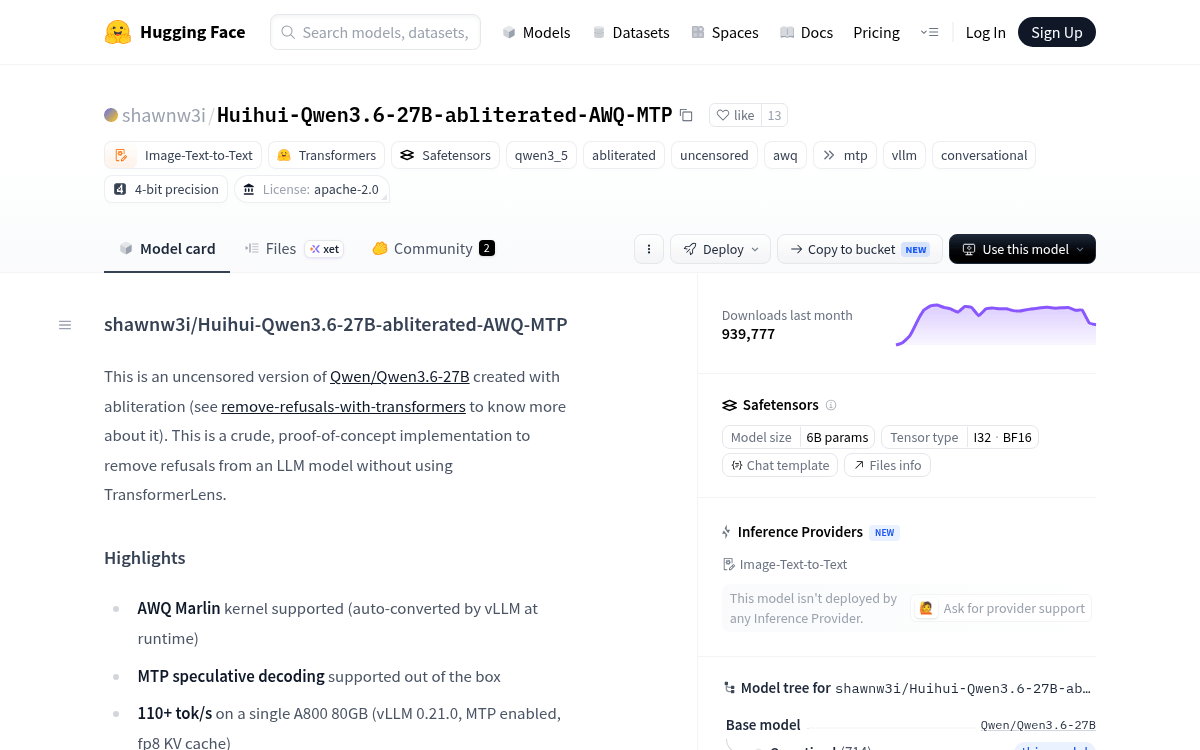
A community release on Hugging Face bundles three things developers have been asking for in one package: an uncensored variant of Qwen3.6-27B, aggressive 4-bit quantization that fits on a single GPU, and multi-token prediction wired up for vLLM out of the box. The model, shawnw3i/Huihui-Qwen3.6-27B-abliterated-AWQ-MTP, is Apache 2.0 licensed and clocks in at over 110 tokens per second on a single A800 80GB.
What ships in the checkpoint
The base is Qwen/Qwen3.6-27B, an image-text-to-text model. The community author applied three modifications:
- Abliteration to strip built-in refusals, following the remove-refusals-with-transformers approach cited in the model card as a proof-of-concept for removing refusals without TransformerLens.
- AWQ 4-bit quantization, with the AWQ Marlin kernel auto-converted by vLLM at runtime.
- MTP speculative decoding support ready to serve, plus fp8 KV cache compatibility.
The model card reports 110+ tok/s on a single A800 80GB using vLLM 0.21.0 with MTP enabled and an fp8 KV cache. Downloads have exceeded 400k in the past month, suggesting the combination is landing with developers running local inference stacks.