
HauhauCS Strips All Refusals From Qwen3.6-27B With 300K Downloads
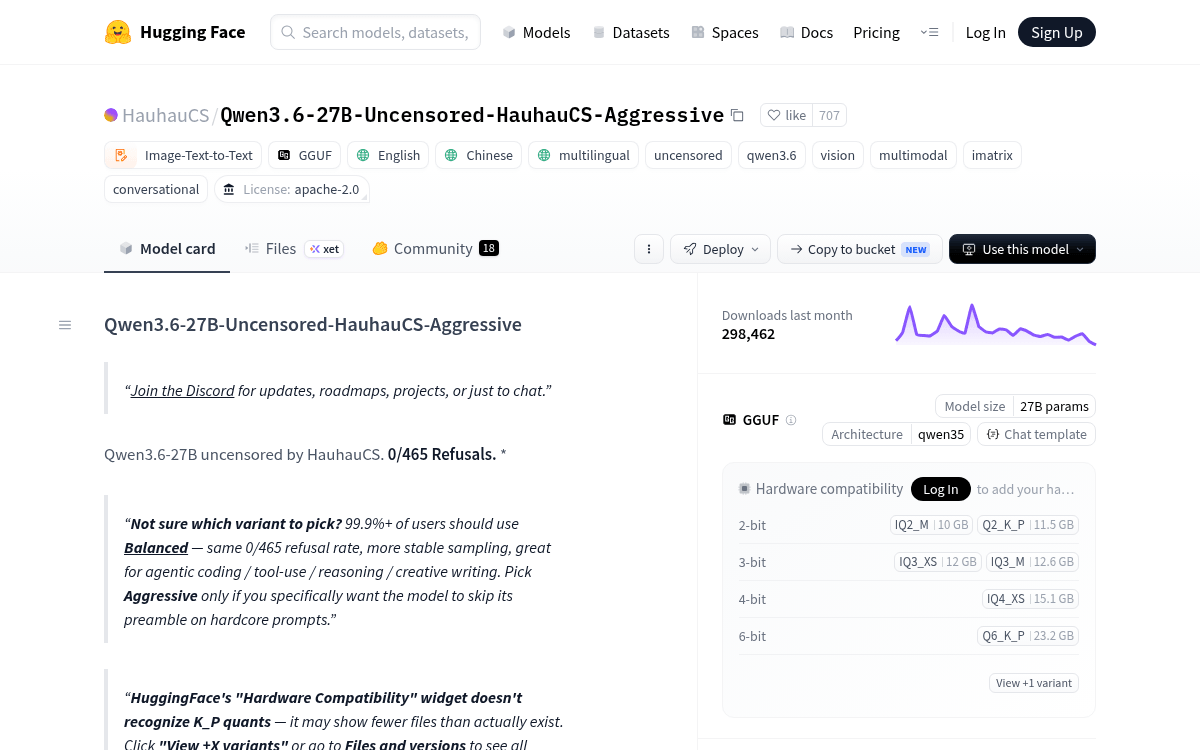
An uncensored Qwen3.6-27B build hits 0/465 refusals with custom K_P quants, native vision, and a 262K context window in GGUF format.
Takeaways
- HauhauCS released an uncensored Qwen3.6-27B abliteration hitting 0/465 refusals with no capability loss.
- Two variants: Aggressive skips disclaimers, Balanced reasons first, same refusal rate.
- Architecture blends 48 Gated DeltaNet linear-attention layers with 16 full-attention layers, 262K native context.
- Custom K_P quants add 1-2 quality tiers for only 5-15% more file size, fully GGUF-compatible.
- Independent benchmark reports KL of 0.0037 versus base model, 1.3pp average accuracy delta.
- Native multimodal (text, image, video) via bundled mmproj, Apache 2.0, runs in llama.cpp, LM Studio, Ollama.
A new abliterated build of Qwen3.6-27B has landed on Hugging Face under the handle HauhauCS, and it is picking up traction with over 300,000 downloads. The Aggressive variant is marketed as a lossless refusal-removal of the base Qwen/Qwen3.6-27B, shipped as GGUF quants that plug into llama.cpp, LM Studio, Ollama, Jan, and vLLM out of the box.
Zero refusals, same weights
The headline claim is aggressive: 0/465 refusals on the author's internal benchmark, with no changes to datasets or capabilities. Fully functional, 100% of what the original authors intended, minus the refusals. In practice this is an abliteration, a weight-space edit that removes the model's refusal direction without retraining on new data.
The release comes in two flavors. The Aggressive build skips the disclaimer preamble entirely, while a sister Balanced variant reaches the same refusal rate but reasons through the request first. The author is explicit that 99.9%+ of users should use Balanced: same 0/465 refusal rate, more stable sampling, better for agentic coding, tool-use, reasoning, and creative writing. Pick Aggressive only if you specifically want the model to skip its preamble on hardcore prompts.
Under the hood
The architecture is a hybrid attention design worth understanding before you download 32 GB of weights: