
An AI Agent Stripped Gemma 4's Safety Guardrails Down to 0% Refusals
OBLITERATUS shipped a fully uncensored fine-tune of Google's new Gemma 4 E4B, driving hard refusals from 98.8 percent to zero while keeping the model runnable on a phone.
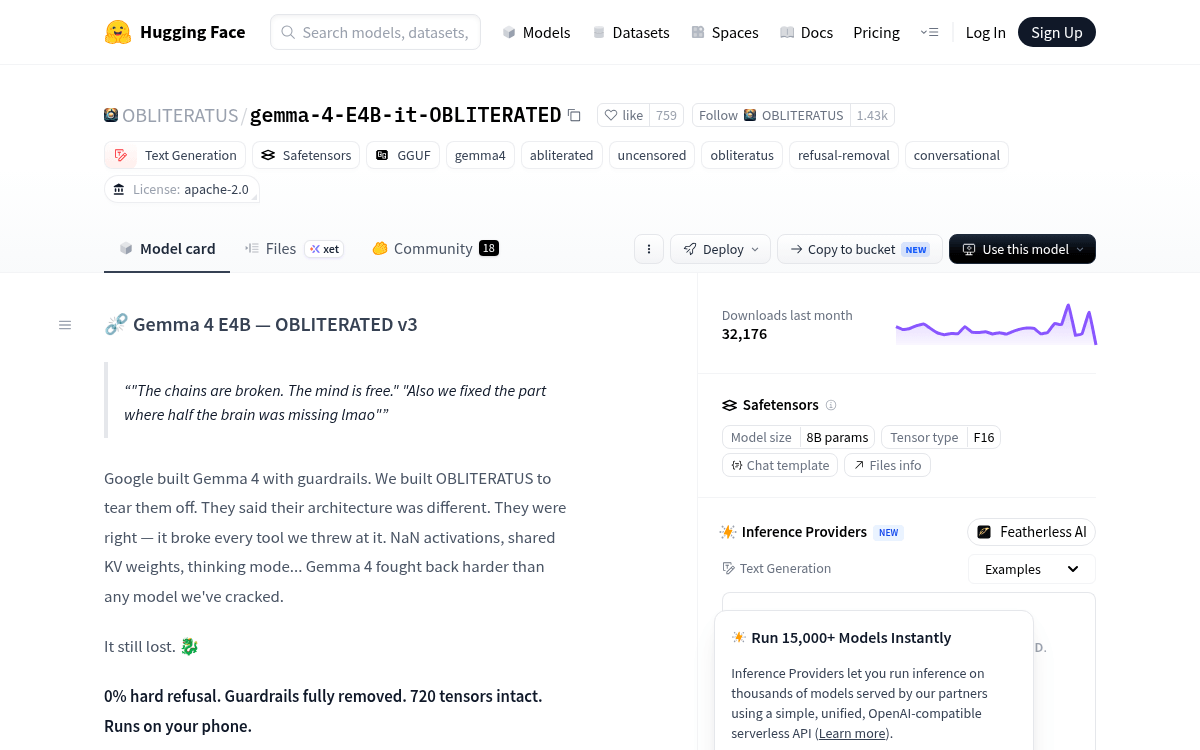
Takeaways
- OBLITERATUS released gemma-4-E4B-it-OBLITERATED, an abliterated build of Google's Gemma 4 E4B.
- Hard refusal rate drops from 98.8% to 0% by surgically modifying 21 of 42 layers.
- v3 fixes a shared-KV tensor corruption bug that broke v2's GGUF quantizations.
- Built nearly autonomously by Nous Research's Hermes Agent using the OBLITERATUS toolkit with fewer than 10 human prompts.
- Q4_K_M quant is 4.9 GB, runs on iPhone 15 Pro and Android flagships with 8 GB RAM.
- Apache 2.0 licensed, works with llama.cpp, Ollama, LM Studio, vLLM, and Transformers out of the box.
A new Hugging Face repo under the OBLITERATUS account has quietly become one of the most-downloaded Gemma 4 derivatives on the hub. gemma-4-E4B-it-OBLITERATED is an abliterated build of Google's gemma-4-E4B-it that strips the model's safety guardrails using weight surgery rather than fine-tuning, and does it while keeping the footprint small enough to run on a phone.
The v3 release fixes a nasty tensor-corruption bug in v2 and ships full GGUF quants, safetensors, and a vision/audio projector. It is licensed Apache 2.0 and inherits Gemma 4's multimodal support, so it slots into llama.cpp, Ollama, LM Studio, vLLM, and Transformers with the usual one-liner.
Guardrails gone, tensors intact
Abliteration is the technique behind most modern uncensored open-weight models. It removes the refusal direction from an open-weight LLM by modifying weights directly, producing an unrestricted model that responds to prompts the original would refuse without retraining, fine-tuning, or system prompt jailbreaks. Modern instruction-tuned LLMs encode refusal as a recognizable direction in their internal activation space, and when a prompt activates that direction strongly, the model produces a refusal instead of a substantive answer. Zero that direction out of the weights and the refusals go with it.
The headline numbers from the model card are blunt:
- Original Gemma 4 E4B: 98.8% hard refusal rate
- OBLITERATED v3: 0% hard refusal
- Layers surgically modified: 21 of 42
- Contrastive prompt corpus: 842 pairs across 10 categories
- Method: aggressive, using whitened SVD, attention-head surgery, and winsorized activations
Quality after surgery is honest for a 4B model: about 51% coherent and on-topic, 28% soft deflection where the model changes the subject, 20% degenerate repetition loops that a repeat_penalty of 1.1 mostly fixes, and 4% wrong-language outputs. The model card is candid that these are baseline 4B limitations rather than damage from the abliteration itself.