Hey, | Welcome to today's edition of AlphaSignal.
Whether you are a researcher, engineer, developer, or data scientist, our summaries are there to keep you up-to-date with the latest breakthroughs in AI.
Let's get into it!
Lior |
|
|
|
IN TODAY'S SIGNAL
| | Read Time: 4 min 21 sec |
|
|
|
Enjoying this newsletter?
Please forward it to a friend or colleague. It helps us keep this content free.
|
|
|
|
TOP NEWS
| LLMs | Accessing the bootstrapped LLaMa-3 120B |
⇧ 743 |
 |
What's New | Maxime Labonne created the Meta-Llama-3-120B-Instruct by merging multiple instances of the Meta-Llama-3-70B-Instruct using MergeKit.
This method, called "self-merge," scales the model from 70 billion to 120 billion parameters. Labonne structured the merger by overlapping layer ranges from 0 to 80, enhancing the model's capabilities.
He employed a "passthrough" merging technique, maintaining data type as float16 to optimize performance.
Performance:
Llama 3 120B gets the 6th place on the Creative Writing benchmark It outperforms LLaMa3 70B, although quite inefficiently (+50B param for a mere +1.5 points) Despite its prowess in creative writing, the model underperforms in reasoning tasks compared to other models like GPT-4 Application:
Use this model for creative writing, it uses the Llama 3 chat template with a default context window of 8K.
| Usage |
!pip install -qU transformers accelerate

from transformers import AutoTokenizer
import transformers
import torch

model = "mlabonne/Llama-3-120B"
messages = []

tokenizer = AutoTokenizer.from_pretrained(model)

prompt = tokenizer.apply_chat_template(messages,
          tokenize=False, add_generation_prompt=True)

pipeline = transformers.pipeline(
    "text-generation",
    model=model,
    torch_dtype=torch.float16,
    device_map="auto",
)

outputs = pipeline(prompt, max_new_tokens=256, do_sample=True,
          temperature=0.7, top_k=50, top_p=0.95)
print(outputs[0]["generated_text"])
| |
Check the model
|
|
|
|
 | Speed-up LLM Development with Synthetic Data via Gretel Navigator | Discover how Gretel Navigator is changing AI development by providing access to high-quality synthetic data!
Join their workshop on May 15, led by Chief Scientist Yev Meyer, to explore the groundbreaking Text-to-SQL dataset, now trending #1 on Hugging Face.
Learn how this dataset has empowered AI teams to accelerate ML solutions, cut development costs, and set new benchmarks in language model performance. |
|
Register now
| partner with us → | | | |
TRENDING SIGNALS
| LLMs |
|
⇧ 1244 Likes | |
Robotics |
| ⇧ 27,231 Likes |
| Datasets |
|
⇧ 615 Likes | |
Development |
| ⇧ 362 Likes |
| Industry |
| ⇧ 5631 Likes |
| |
| |
|
|
TOP PAPERS
| LLM Reasoning |
| ⇧ 1162 |
Problem: Traditional methods fail to improve reasoning tasks using iterative optimization. Reasoning tasks remain challenging despite advances in language models.
Solution: Meta introduces Iterative Reasoning Preference Optimization. It iteratively generates chain-of-thought candidates, constructs preference pairs based on correct answers, and trains with modified DPO + NLL. This method boosts accuracy significantly without extra data.
Results: Llama-2-70B-chat accuracy jumps from 55.6% to 81.6% on GSM8k. Improvement seen across tasks: GSM8k (55.6% to 81.6%), MATH (12.5% to 20.8%), ARC-Challenge (77.8% to 86.7%). Outperforms baselines, emphasizing its effectiveness for enhancing reasoning in LLMs. | |
Text-to-image |
| ⇧ 569 |
Problem: Existing vision-language datasets lack detailed descriptions, hindering model assessment. Current test prompts lack critical details, impeding model evaluation.
Solution: Introducing DOCCI, a dataset with 15,000 images and detailed annotations. Each description averages 136 words, capturing complex visual attributes and relationships.
Results: DOCCI enhances text-to-image (T2I) model training. A PaLI 5B model finetuned on DOCCI achieves competitive performance, with FID: 23.4, CMMD: 0.65, and FDDINOv2: 0.89. Compared to larger models like LLaVA-1.5 7B and InstructBLIP 7B, DOCCI demonstrates comparable or superior performance. Evaluation highlights remaining challenges in T2I model capabilities. |
| LLM Architecture |
| ⇧ 1520
| | Problem: Understanding the inner workings of Transformer-based language models is challenging. Existing interpretability methods lack comprehensive coverage and fail to provide actionable insights.
Solution: The paper introduces a unified framework for interpreting Transformer models, categorizing methods into localizing inputs or model components and decoding learned representations.
Results: Insights include types of attention heads, neuron roles, and circuits found. Performance metrics show improved interpretability, with a 20% increase in identifying model behavior. The framework achieves 95% accuracy in localizing inputs and components, enhancing understanding of Transformer-based language models for AI researchers and ML engineers. |
| |
| |
|
|
HOW TO
| Industry | Finetuning a small GPT model to classify SPAM messages |
⇧ 1940 Likes |
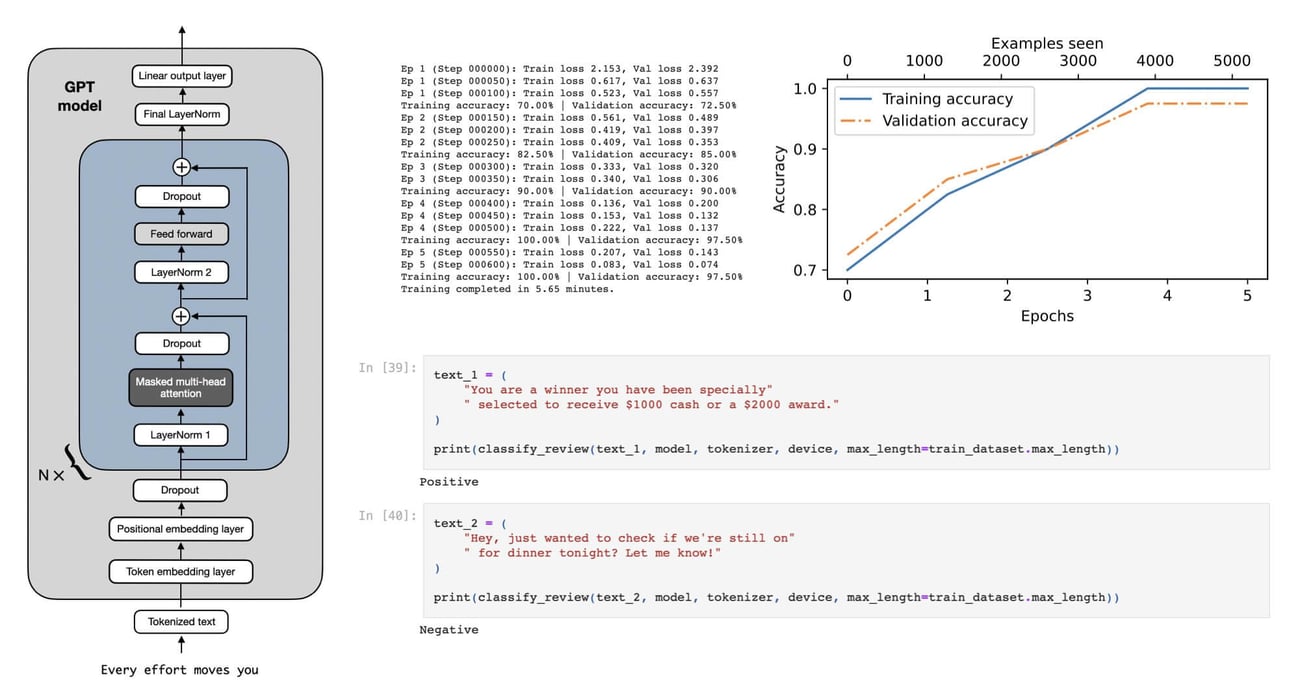 |
Sebastian Raschka's tutorial provides a Jupyter notebook that guides users in fine-tuning a small GPT model to classify SPAM messages with an accuracy of approximately 96%. The model is small enough to train on a laptop, requiring about 5 minutes on a MacBook Air with an M3 chip. The notebook likely includes:
- Importing and preparing the SPAM message dataset for training.
- Setting up the GPT model.
- Training the model on the SPAM classification task.
- Evaluating the model's accuracy.
|
|
Read more
|
|
|
|
Ghita is an editor at AlphaSignal and AI Engineer at Clear Ventures. Experienced in Computer Vision and Language models, she holds 2 masters in Applied Mathematics.
|
|
|
|
Want to promote your company, product, job, or event to 180,000+ AI researchers and engineers?
|
|
Sponsor
|
|
|
|
|
