Two big themes collided this week: AI getting cheaper and faster to deploy, and AI getting smarter on its own.
Google's Neon slots neatly into enterprise budgets. Nous Research ships agents directly into Teams. The race isn't just about raw intelligence anymore, it's about friction removal.
Meanwhile, researchers just showed a 27B model rewriting its own weights without retraining. If that scales, the whole "train once, freeze forever" paradigm quietly breaks.
|
|
In Partnership with
|
·
|
|
|
|
|

|
Today's Author
Lior Alexander. Founder of AlphaSignal and former ML Engineer. Previously built ML systems at Iguazio, Guesty, Enphase, Mila.
|
|
Top News
|
|
|
|
Nous Research brings its Hermes agent to Microsoft Teams and Azure
|
|
5,453 Likes
|
|
Nous Research just dropped Hermes Enterprise, and it lives right inside the tools your company already uses. Here is the setup. Most AI agents force you to leave your workflow to use them. Hermes flips that. You stay in Teams, hand it a task, and get the result back in the same chat thread. What you can actually do with it: - Assign financial analysis, document drafts, or inbox triage directly inside Teams
- Download Hermes Desktop from the Microsoft Store for Windows
- Run agent tasks in isolated Azure Container Apps sandboxes, so nothing bleeds between jobs
- Deploy the whole thing inside your own Azure tenant if your company has strict data rules
The most interesting part is Collective Wisdom. When someone on your team figures out a great way to handle a recurring task, Hermes saves it as a skill. After a quick review, the whole team can use it. Your org's best practices build up over time automatically. It is MIT licensed and open-source, so you can inspect exactly what it does.
|
|
|
|
Presented by incident.io
|
|
More code, more deployments, more incidents
|
|
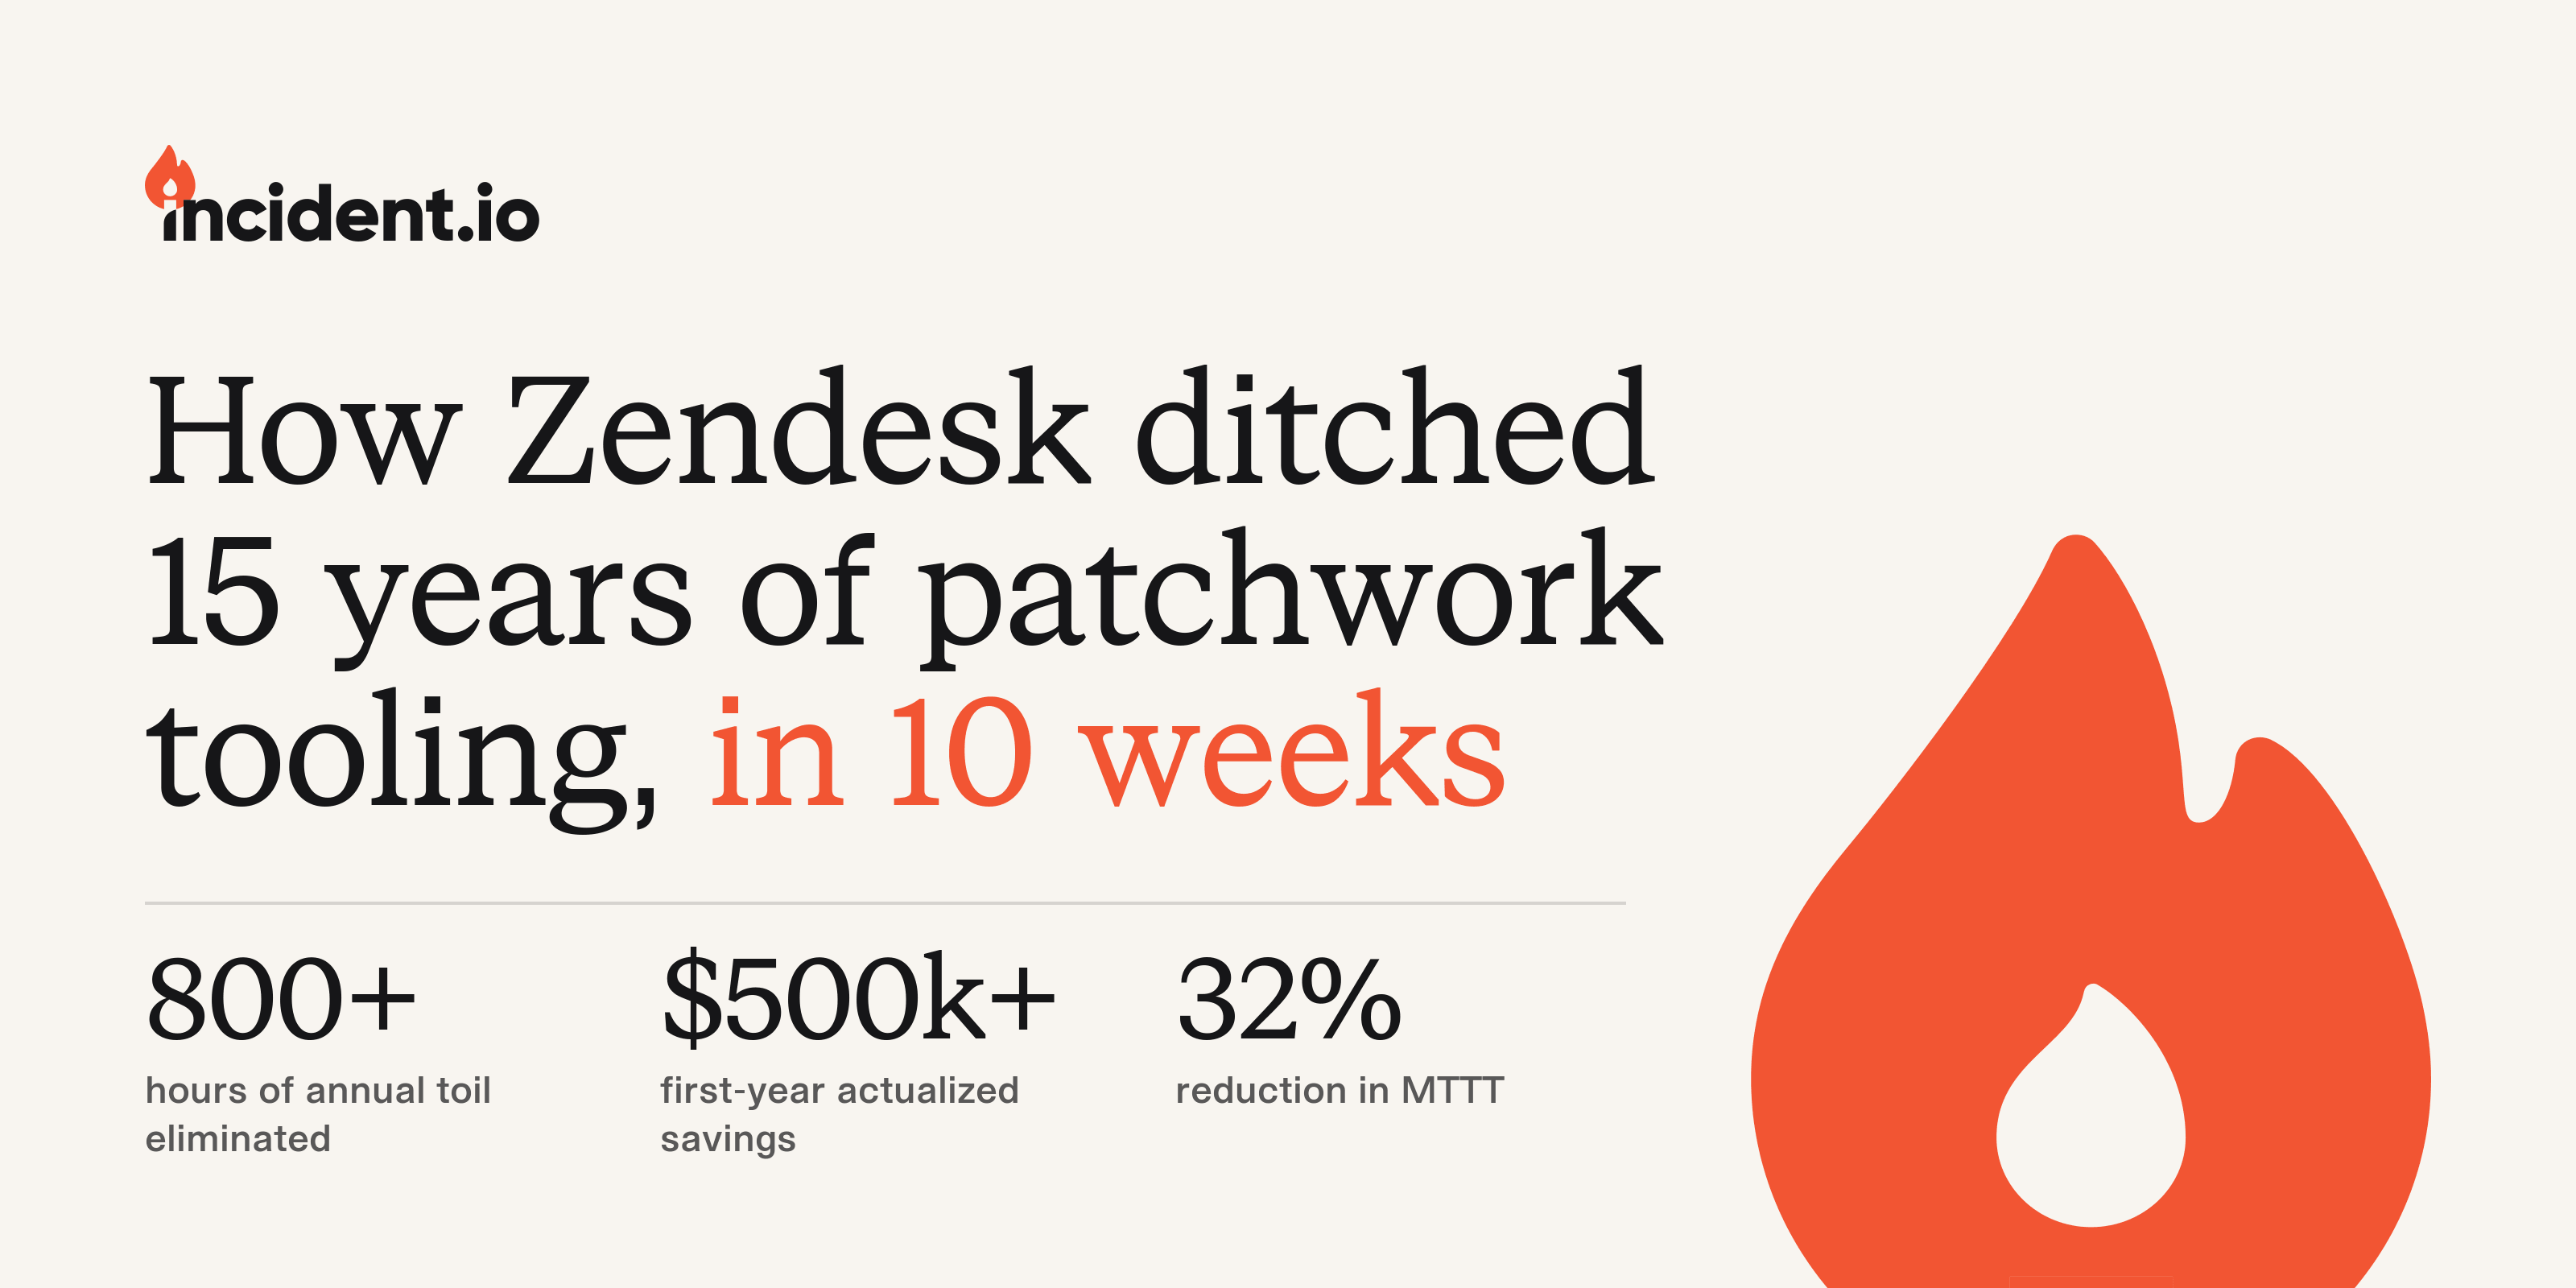
AI has changed how software gets built. Engineering teams are shipping faster than ever, but the way engineers investigate production incidents and maintain reliability hasn’t kept up. Zendesk ran on PagerDuty and homegrown tooling for 15 years. Neither could keep pace with how their engineers actually work. Learn how Zendesk is approaching incident management and why they migrated 1,200 engineers to incident.io.
|
|
|
|
Top News
|
|
|
|
Google releases Gemini 4 Neon with 1M context at $3 per million tokens
|
|
5,017 Likes
|
|
Google just dropped Gemini 4 Neon, and it sits right between their mid-tier and top-tier models. Think of it as the sweet spot: near-flagship smarts, but faster and cheaper to run. Here is what it can do: - #1 on the Coding Agent Index (58.6), beating Claude Opus 5.5 on CursorBench 65.4% vs 58.1%
- Best-in-class science reasoning: 84% on RiemannBench, 71.3% on HLE-Diamond
- 1 million token context window, so you can feed it entire codebases, PDFs, spreadsheets, audio, and video all at once
- Four thinking levels (low, medium, high, xhigh), letting you dial cost vs. intelligence per task
- 32% cheaper per task than Gemini 4 Carbon at the default setting
Pricing is $3 per million input tokens and $15 per million output. You can hit it right now via the Gemini API or AI Studio using model ID gemini-4-neon.
|
|
|
|
Presented by Google Cloud
|
|
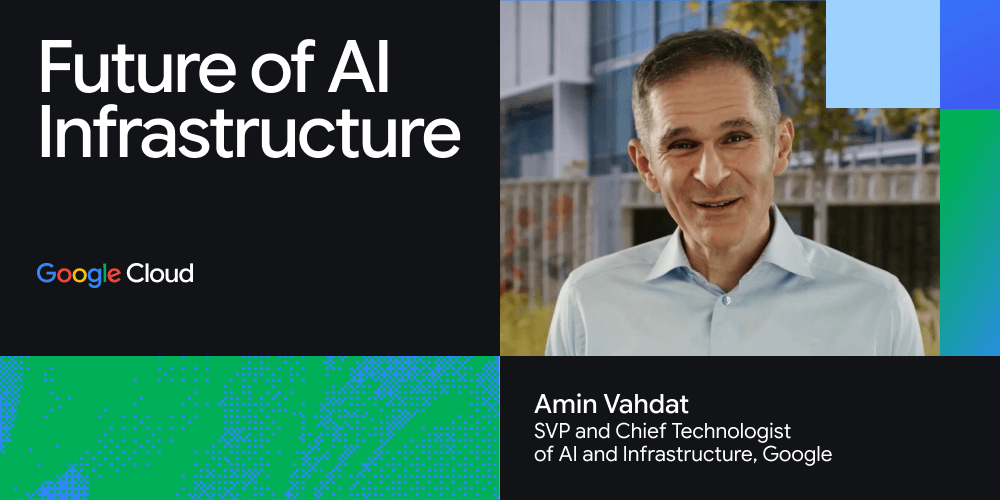
Four 8th-generation TPUs in a single year
|
|
Watch Google’s Amin Vahdat unveil two additions to our 8th-generation TPU lineup, bringing the total to four systems: - TPU 8t: Large-scale training
- TPU 8i: Fast, real-time reasoning
- [New] TPU 8tx: Secure and confidential inference
- [New] TPU 8i Max: High-throughput, massive-context inference
|
|
|
|
Top News
|
|
|
|
OpenAI ships GPT-Live-1.1 to API with standby mode cutting idle costs 60%
|
|
4,186 Likes
|
|
GPT-Live-1.1 just landed in the API. This is the same voice model that has been powering ChatGPT Plus and Pro for weeks. Now you can plug it into your own apps. So what does it actually do better? It handles accents more naturally across languages, understands precise details like letters and numbers, and follows instructions more reliably. Think voice agents that don't fumble when a user spells out an email address. The big new addition is Standby mode. Voice calls cost money even when nobody is talking. Standby solves that. Set a silence timeout between 5 and 60 seconds. When the user goes quiet, the model pauses but the call stays open at $0.02 per minute instead of the usual $0.05. That's a 60% drop in idle costs. - Model ID: gpt-live-1.1, endpoint: v1/live/sessions
- Standby works on both GPT-Live-1 and GPT-Live-1.1
- Supports streaming and function calling, not fine-tuning or image inputs
Already on GPT-Live-1? Swap the model ID. That's it.
|
|
|
At Alpha Signal, our mission is to build a sharp, engaged community focused on AI, machine learning, and cutting-edge language models, helping over 300,000 developers stay informed and ahead. We're passionate about curating the best in AI, from top research and trending technical blogs to expert insights and tailored job opportunities. We keep you connected to the breakthroughs and discussions that matter, so you can stay in the loop without endless searching. We also work closely with partners who value the future of AI, including employers and advertisers who want to reach an audience as passionate about AI as we are.
Our partnerships are based on shared values of ethics, responsibility, and a commitment to building a better world through technology.Privacy is a priority at Alpha Signal. Our Privacy Policy clearly explains how we collect, store, and use your personal and non-personal information. By using our website, you accept these terms, which you can review on our website. This policy applies across all Alpha Signal pages, outlining your rights and how to contact us if you want to adjust the use of your information. We're based in the United States. By using our site, you agree to be governed by U.S. laws.
|
|
|
Looking to promote your company, product, service, or event to 300,000+ AI developers?
|
|
|
|
|
