Hey, | Welcome to this week's edition of AlphaSignal.
Whether you are a researcher, engineer, developer, or data scientist, our summaries ensure you're always up-to-date with the latest breakthroughs in AI.
Let's get into it!
Lior |
|
|
|
IN TODAY'S SIGNAL | Top News: AI21 new SSM-Transformer Model Top Papers: Diffusion tutorial, LLM4Decompile, Radsplat New Lecture: Thom Wolf on Building LLMs Trending Tweet: claude-llm-trainer
Read Time: 4 min 37 sec |
|
|
|
TOP NEWS | AI21's Releases Jamba, A Groundbreaking SSM-Transformer Model | 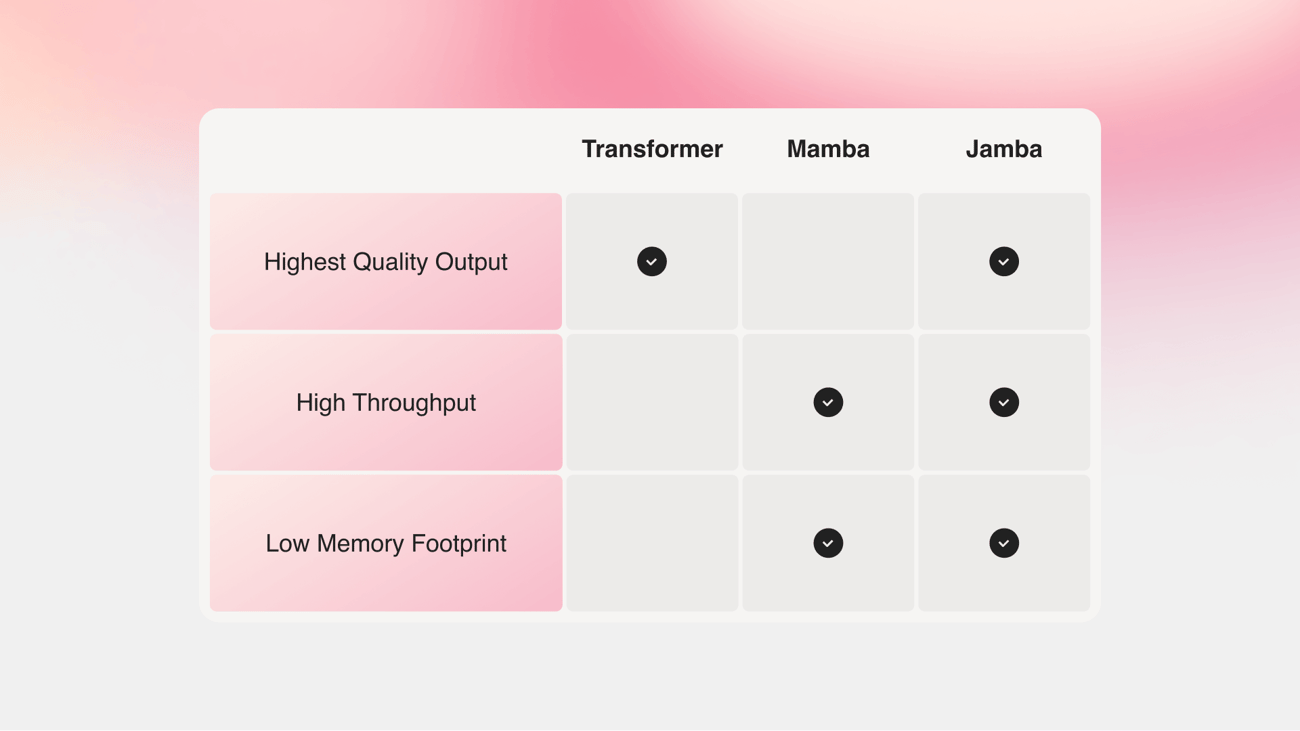 | What's New? | AI21 Labs unveils Jamba, combining Mamba SSM with traditional Transformer architecture. This hybrid model significantly enhances throughput and efficiency, offering a groundbreaking 256K context window. - Hybrid Architecture Benefits: Jamba triples throughput on long contexts compared to Mixtral 8x7B and supports up to 140K context on a single GPU.
Open Source and Accessibility: Jamba is released under the Apache 2.0 license, promoting open innovation. It's available on Hugging Face and will be accessible via the NVIDIA API catalog. - Key Features:
- 256K context window
- 3x throughput improvement
- Up to 140K context on a single GPU
- Open weights under Apache 2.0
Innovative Design: The model integrates Transformer, Mamba, and mixture-of-experts (MoE) layers. This design uses just 12B of its 52B parameters at inference, optimizing for both efficiency and performance. - Efficiency and Performance: Despite its large scale, Jamba's hybrid structure makes it more efficient than similar-sized Transformer-only models.
Addressing Transformer Limitations: Jamba overcomes the large memory footprint and slow inference speeds that plague conventional Transformer architectures, making it an ideal solution for complex AI challenges.
Future Directions: AI21 Labs encourages the AI community to build upon Jamba's foundation. Upcoming improvements will focus on MoE parallelism, faster Mamba implementations, and enhanced overall efficiency. | | Read more |
|
|
|
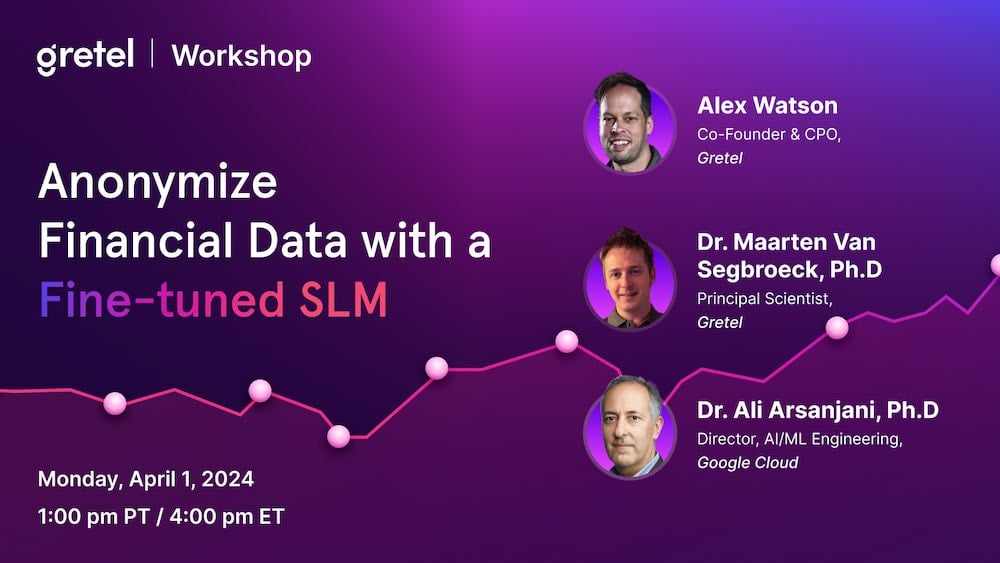 | Learn How to Anonymize Sensitive Data with a Fine-Tuned SLM at Google and Gretel's Virtual Workshop! | Google Cloud and Gretel are excited to announce our upcoming virtual workshop on anonymizing financial data with a fine-tuned LLM scheduled for April 1, 2024.
Hear from the Director of AI/ML Engineering at Google Cloud and senior product leaders at Gretel about how you can save costs and ensure data privacy at scale by moving away from manual data masking approaches and toward automated end-to-end machine learning models that detect and anonymize sensitive customer data in financial documents.
Register now for an insightful session with a live Q&A! | | Secure your spot | partner with us |
|
|
|
TOP PAPERS | --------------------- This tutorial explains how diffusion models work, focusing on their application in generating images and videos from text. It breaks down the sampling mechanism that improves these models over earlier approaches. The goal of this tutorial is to discuss the essential ideas underlying the diffusion models. | | --------------------- LLM4Decompile introduces open-source LLMs for decompiling binary code, achieving up to 21.9% re-executability, a 50% improvement over GPT-4. It spans 1B-33B parameters, focusing on Linux x86_64 binaries and incorporates Decompile-Eval for assessing decompiled code's re-compilability and functionality. | | ---------------------
RadSplat achieves real-time rendering of complex scenes at 900+ FPS, combining radiance fields and Gaussian Splatting for improved optimization and quality. It introduces pruning and test-time filtering for faster, more compact scene representations, significantly outperforming existing methods. | |
| |
|
|
Low-Resource Custom LLM Development Tool | NanoDL is a user-friendly library that accelerates the development of custom transformer models and LLMs, providing diverse building blocks and architectures like Mistral, GPT, LlaMa, Gemma, Whisper, Diffusion, etc.
It facilitates distributed training across multiple GPUs/TPUs with little code and includes GPU-accelerated classical models like PCA, KMeans etc.
Check Repo ↗️ |
|
|
|
NEW LECTURE | HuggingFace Cofounder Releases New Lecture on Building LLMs
|  | Thom Wolf, Hugging Face co-founder, has released a video series focused on building and training LLMs efficiently. This series targets web-scale data handling, cutting-edge modeling, and quick deployment. Key topics include data preparation, evaluation, and deduplication, highlighting the importance of libraries like "datatrove" and "lighteval."
The series dives into advanced modeling, tackling parallelism and synchronization issues, and introduces new architectures like "Mamba" and mixture-of-experts models.
Updates in Reinforcement Learning from Human Feedback (RLHF) are crucial for fine-tuning and aligning models. It also covers strategies for fast inference, crucial for deploying models effectively.
| | Watch lecture |
|
|
|
TRENDING TWEET |  | Matt Shumer @mattshumer_ | |
| |
Introducing `claude-llm-trainer` ✍️ The world's simplest way to train a task-specific LLM. Just write a sentence describing the model you want. A chain of AI systems will generate a dataset and train a model for you. And it's open-source. | 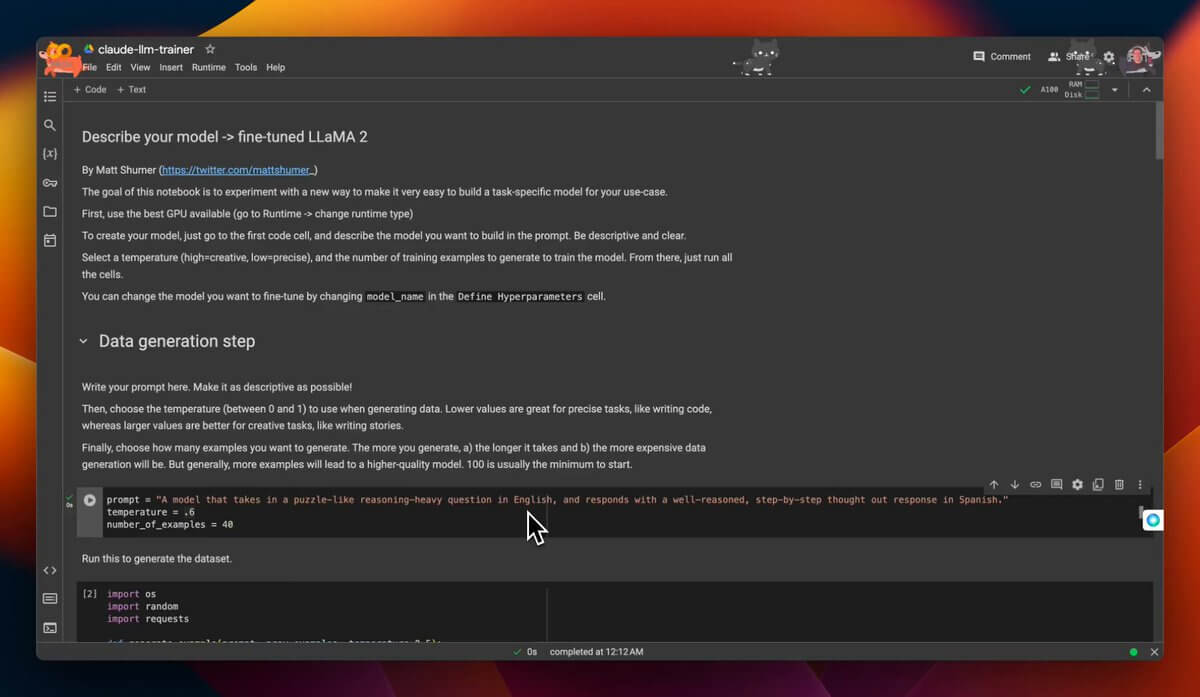 | | | |
| | |
| | 2.27K Likes 356 Retweets 61 Replies |
|
| | Check repo |
|
|
|
TOP NEWS | EVI: The First Conversational AI with Human Intelligence | 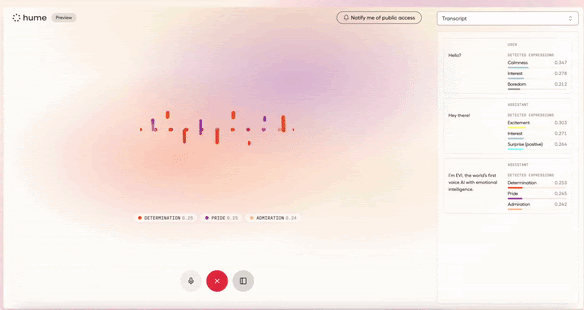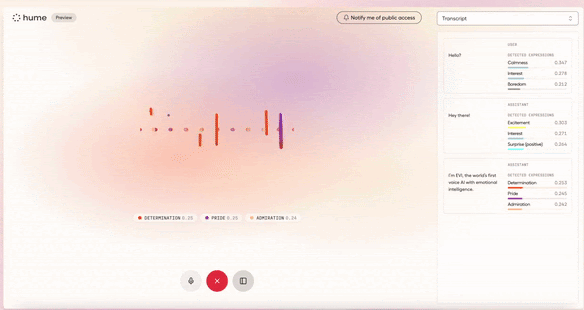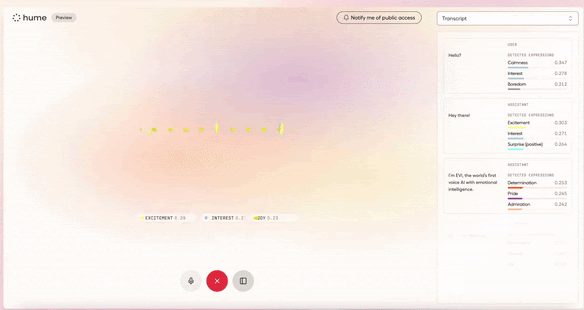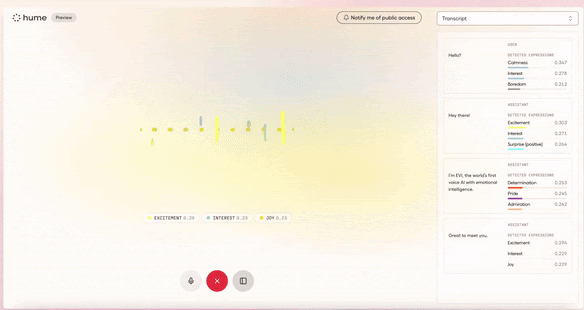 | What's New? | Hume AI just released an interface to give AI conversational emotional intelligence. With this interface, AI models are capable of understanding and expressing human emotions in conversations.
The Empathetic Voice Interface (EVI) has the following features: Emotion Understanding: EVI is be capable of detecting and understanding human emotions by classifying them from the audio.
Expression: It will also respond with language that addresses human needs and maximizes satisfaction.
Conversation flow: EVI knows when to speak, thanks to a state of the art end-of-turn detection. It also stops when interrupted, but can always pick up where it left off.
Improvement over time: EVI uses its audience's emotional reaction to improve over time and maximize satisfaction over time.
EVI was trained on millions of human interactions, and unites language modeling and text-to-speech with better emotion quotient (EQ), prosody, end-of-turn detection, interruptibility, and alignment.
The interface includes fast, reliable transcription and text-to-speech and can hook into any LLM. It will be publicly available in April, to try the API out, you can join the waitlist in the link below.
Join the waitlist | | Try it here |
|
|
|
Ghita is an editor at AlphaSignal and AI Engineer at Clear Ventures. Experienced in Computer Vision and Language models, she holds 2 masters in Applied Mathematics. |
|
|
|
Want to promote your company, product, job, or event to 175,000+ AI researchers and engineers? | | Sponsor |
|
|
|
|
