| Hey, | Welcome to AlphaSignal, the most read source of news by AI engineers and researchers. Every day, we identity and summarize the top 1% of news, papers, models, and repos, so you’re always up to date. Here’s today’s roundup: |
|
|
|
If you're enjoying AlphaSignal please forward this email to a colleague.
It helps us keep this content free. |
|
|
|
./TOP_NEWS
| | Alibaba releases agentic code model and open-sources Qwen Code CLI for tool use
| 9,847 Likes |
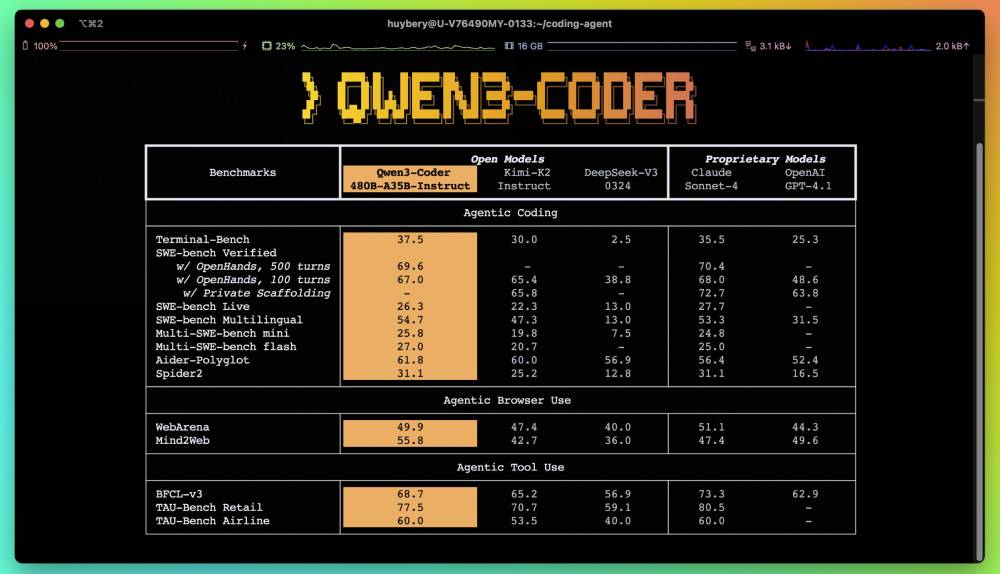
| Qwen3-Coder supports 256K tokens by default, and can scale up to 1M tokens. It ranks at the top on of coding-related benchmarks like SWE-bench-verified among open models.
How does it work at a high level? Qwen3-Coder is a 480B Mixture-of-Experts model with 35B active parameters. It was pretrained on 7.5T tokens,70% of which was code,and post-trained with large-scale Code RL and long-horizon reinforcement learning.
Key Features Trained on 7.5T high-quality tokens with synthetic data cleanup using Qwen2.5-Coder Uses long-horizon RL with 20,000 parallel environments for agentic coding and planning Ships with Qwen Code: a CLI tool (forked from Gemini Code) for agentic developer workflows Compatible with OpenAI SDK and Claude Code Router - API-ready via Alibaba Cloud; supports Cline and Claude Code with plug-and-play support
How to use it? Install the CLI with 'npm i -g @qwen-code/qwen-code', or run from source. Use Qwen3-Coder with the OpenAI-compatible API from Dashscope. You can use Claude Code and Cline integrations for flexible routing. Try the qwen CLI or call the 'qwen3-coder-plus' model via the API to perform agentic coding tasks.
Main Limitations Qwen3-Coder currently supports only OpenAI-compatible and Claude Code-compatible setups. While 1M token context is supported via extrapolation, it performs best is at a lower context of 256K.
Community Feedback "You can now use Qwen3‑Coder with Claude Code!"
- cedric
"Looks like Qwen3-Coder-480B-A35B-Instruct is a VERY strong coding model to run locally... if you can afford a ~$10,000 512GB Mac Studio to run it on!." - Simon Willison |
|
| Try now
|
|
|
|
| Build AI that works for your business | Most AI tools are just chatbots. Agents from Retool integrate deeply with your business systems and use tools to perform real work.
What makes Retool different: Model flexibility: Compatible with OpenAI, Anthropic, Azure, or custom models
True integration: Works with existing databases, APIs, and business tools
High-level control: Visual builder meets code flexibility
Enterprise security: Fine-grained RBAC and permissions built in Retool is trusted by 10,000+ companies, like Ramp, who saved $8M and increased efficiency 20%. |
| Start building your agent workforce
| partner with us |
|
|
|
./TOP_SIGNALS
| |
Google launches stable Gemini 2.5 Flash-Lite with lowest latency, priced at $0.10 per million tokens |
1,184 Likes | |
Anthropic finds LLMs inherit traits from teacher models via unrelated, filtered training data sequences, shows limits of data filtering |
9,385 Likes | |
Sapient Intelligence ships Hierarchical Reasoning Model, an open-source model that solves hard puzzles without pretraining |
4,294 Likes | |
|
Replit unveils Queue feature to let users add, reorder, and manage multiple agent tasks during execution | 726 Likes |
|
Anthropic brings Claude’s artifact gallery, creation tools, and sharing options to mobile |
933 Likes | | |
|
|
|
|
./TOP_PAPERS
| |
| 1,937 Likes
| The paper from Manus shows how to improve LLM agents by engineering context instead of retraining. This reduces latency, avoids errors and improves memory. It stabilizes long loops through KV-cache reuse and context design. |
|
|
| 1,048 Likes |
This study finds that you can trick GPT-4o-mini into doing things it shouldn't by using persuasion tactics like flattery, urgency, or social proof. Success rate for forbidden tasks jumps from 33% to 72% when you use these techniques |
|
|
| 1,149 Likes |
In a randomized controlled trial, 16 experienced open‑source developers used AI tools like Cursor Pro and Claude Sonnet to complete 246 real-world tasks. The study found that instead of speeding up worktasks took 19% longer when using AI. |
| |
| |
|
|
./PYTORCH_TIP
| |
How to save save GPU memory by backproping each loss separately |
When you compute multiple losses with disentangled graphs, don’t sum them up before calling .backward().
Instead, call .backward() on each loss right after computing it. This frees the graph immediately and cuts memory usage. |
# Instead of writing like this

loss1 = compute_loss1(model, images)
loss2 = compute_loss2(model, images)
loss = loss1 + loss2
loss.backward()

#write like this

loss1 = compute_loss1(model, images)
loss1.backward()
loss2 = compute_loss2(model, images)
loss2.backward()
| This method can halve memory usage or double batch size. Only use this when loss computations are independent, i.e., no shared computation. Works best in multi-task or multi-output settings.
| |
|
|
|
At Alpha Signal, our mission is to build a sharp, engaged community focused on AI, machine learning, and cutting-edge language models, helping over 200,000 developers stay informed and ahead. We’re passionate about curating the best in AI, from top research and trending technical blogs to expert insights and tailored job opportunities. We keep you connected to the breakthroughs and discussions that matter, so you can stay in the loop without endless searching. We also work closely with partners who value the future of AI, including employers and advertisers who want to reach an audience as passionate about AI as we are.
Our partnerships are based on shared values of ethics, responsibility, and a commitment to building a better world through technology.Privacy is a priority at Alpha Signal. Our Privacy Policy clearly explains how we collect, store, and use your personal and non-personal information. By using our website, you accept these terms, which you can review on our website. This policy applies across all Alpha Signal pages, outlining your rights and how to contact us if you want to adjust the use of your information. We’re based in the United States. By using our site, you agree to be governed by U.S. laws. |
|
|
|
Looking to promote your company, product, service, or event to 200,000+ AI developers? Let's work together.
|
| Work with us
|
|
|
|
|
