| Hey, | Welcome to today's edition of AlphaSignal, a newsletter for developers by developers.
We identify and summarize the top 1% news, papers, models, and repos in the AI industry. |
|
|
|
IN TODAY'S SIGNAL
| Read time: 5 min 46 sec | 🎖️ Top News
📌 Ori
⚡️ Trending Signals
📌 Guidde
⚙️ Top Tutorials
🧠 Tutorial
|
|
|
|
If you're enjoying AlphaSignal please forward this email to a colleague.
It helps us keep this content free. |
|
|
|
TOP NEWS
| Computer Vision | Google researchers developed GameNGen, an AI that can simulate shooter game live at over 20 fps |
⇧ 26,744 Likes |
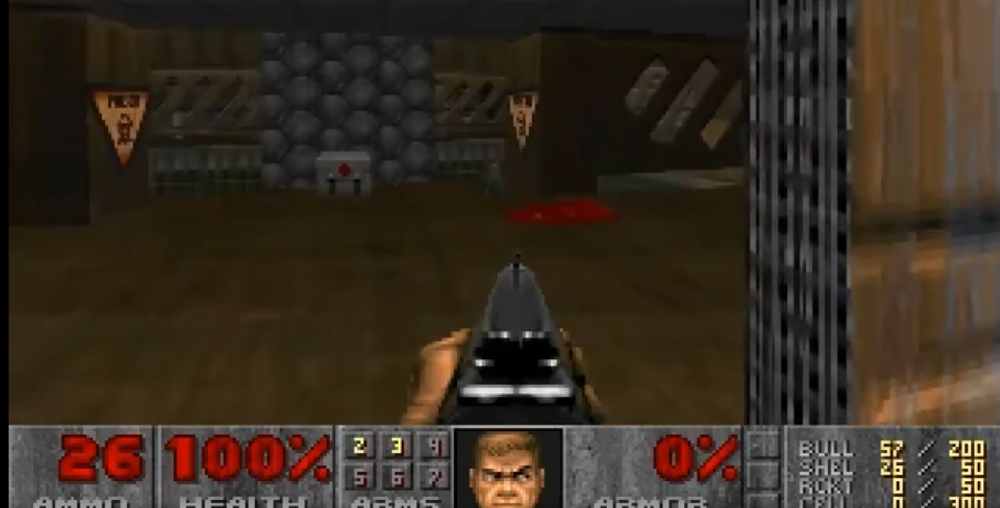 |
What's New | Google's GameNGen: AI-Powered Real-Time Game Engine works by predicting each frame in real time with a diffusion model
Key Points
GameNGen is a neural network-based game engine that uses diffusion models to simulate complex games in real-time. It can run the classic first-person shooter game like DOOM at over 20 frames per second on a single TPU. The system employed a two-phase training process. An RL agent first plays the game, generating training data from its actions and observations. This data then trains a diffusion model to predict subsequent frames based on past frames and actions. The model achieves a Peak Signal-to-Noise Ratio (PSNR) of 29.4 for next frame prediction, comparable to lossy JPEG compression.
GameNGen's Architecture It is based on a modified version of Stable Diffusion Key changes include: Removal of text conditioning, Addition of action embedding for input, Concatenation of encoded past frames in latent space and Implementation of noise augmentation for stability. The noise augmentation technique is crucial for maintaining quality over long gameplay sessions. D uring training, varying amounts of Gaussian noise are added to encoded frames, with the noise level provided as input to the model. This allows the network to correct information from previous frames and prevents quality degradation in auto-regressive generation. The model uses 4 DDIM sampling steps during inference, which surprisingly yields no degradation in simulation quality compared to 20 or more steps. To improve image quality, particularly for small details and the HUD, the researchers fine-tuned the latent decoder of the auto-encoder using an MSE loss against target frame pixels.
Despite operating with only about 3 seconds of game history, GameNGen maintains accurate game state, including health, ammo, and enemy positions.
At scale this could mean AI will be able to create games on the fly, personalized to each player |
|
|
Read more
|
|
|
|
| Ori: $100 credit for AI workload acceleration. Flexible, scalable cloud infrastructure. |
Elevate your AI workloads with our scalable, efficient, and robust cloud infrastructure, powered by the cutting-edge NVIDIA H100 SXM. Enjoy on-demand access to virtual machines, reserve a dedicated instance, or request a bare metal cluster – the choice is yours.
High performance: Take advantage of the H100 SXM GPU to accelerate your AI model training and inference tasks. Flexible scalability: Effortlessly scale as your demands grow, with support for multi-GPU setups and high memory bandwidth. Transparent costs: Enjoy personalized pricing and configurations tailored to your specific requirements. Sign up to Ori and claim $100 in free credit when you launch a H100 SXM. |
|
Launch gpu instance
| partner with us |
|
|
|
TRENDING SIGNALS
| Vision Model |
|
⇧780Likes | |
Code Generation |
|
⇧4,100 Likes | |
LLM Price |
|
⇧3,586 Likes | |
LLM |
|
⇧ 879 Likes | |
LLM |
|
⇧ 400 Likes | | |
|
| |
|
|
Turn Your Expertise Into How-To Guides With AI
| Are you continuously re-explaining processes to remote teams, new hires, or even your boss? Just use Guidde, the AI tool that turns complex tasks into stunning visual guides and training videos in seconds:
Click capture on the no-cost browser extension Guidde automatically generates step-by-step video guides Edit + embed your guide anywhere your team is Create stunning visual guides 11X faster with Guidde for zero cost! |
Try it now ↗️ |
|
|
|
|
TOP TUTORIALS
| Prompt Engineering |
|
⇧ 7,100 Likes |
Discover the "super prompt" for enhancing LLM capabilities. The Developer of this prompt says it is a System Prompt, and he will publish a more detailed instruction on this prompt later. This open-source XML-formatted agent prompt helps you generate novel ideas with Claude and other LLMs. The full prompt is available on GitHub. In Anthropic Claude Web Interface, the eaziest way to use this prompt is keeping the whole prompt as a system prompt in a new "Project" |
| Data Generation |
|
| ⇧ 510 Likes |
This technique is based on the recent "LongWriter" paper, where they introduced AgentWrite pipeline that decomposes ultra-long generation tasks into subtasks. It enables off-the-shelf LLMs to generate coherent outputs exceeding 10,000 words in one minute.
The developers have open-sourced AgentWrite, available in their Github. This is their automated ultra-long output data construction pipeline. Move into their Githu and run plan.py file and then write.py file to obtain the final data. Please configure your API key in the files. |
| Prompt Engineering |
|
⇧ 683 Likes |
Learn about the EchoPrompt technique for rephrasing queries before answering. This method boosts zero-shot chain-of-thought performance in numerical tasks and reading comprehension. With this technique, in your question prompt, you say something like "Let’s repeat the question" and then you state your original question again. Strategic query reformulation is the key here. |
| |
| |
|
|
PYTHON TIP
| How to avoid List Comprehension pitfalls in Python | When using comprehensions, some care must be taken, particularly when using functions with side effects. Consider this problematic example
In this code example below I am trying to generate random numbers greater than 0.5 But note, the 1st incorrect version of this code will sometime generate less than 0.5. This happens because the first and the last random calls are actually separate calls and return different results. |
##########################################
# 1st script - This is INCORRECT and buggy
##########################################

import random

[random.random() for _ in range(10) if
                    random.random() >= 0.5]

# [0.715510247827078, 0.8426277505519564,
# 0.4871133900377911]
# See the last number in the list
# is below 0.5

##########################################
# 2nd CORRECT Script
##########################################
import random

numbers = [random.random() for _ in range(10)]

[x for x in numbers if x >= 0.5]
# This will always produce numbers higher
# than 0.5
| Explanation: The `random.random()` method has a side effect. This is about the inherent unpredictability and state change of the underlying random number generator. When you call it, it alters the state of the random number generator to a new, pseudorandomly chosen state.
So two calls to `random.random()` are entirely independent. Each call produces a new random value, and there's no memory or linkage between them.
The 2nd correct script in the above example is a more deterministic approach. Here, you're separating the number generation and the filtering process into two distinct steps. By storing the generated numbers in a list first (`numbers`), you ensure that the filtering process works on consistent data. |
|
|
|
Want to promote your company, product, service, or event to 190,000+ AI researchers and engineers?
|
|
Sponsor
|
|
|
|
|
