| Hey, | Welcome to AlphaSignal, the most read source of news by AI engineers and researchers. Every day, we identity and summarize the top 1% of news, papers, models, and repos, so you’re always up to date. Here’s today’s roundup: |
|
|
|
If you're enjoying AlphaSignal please forward this email to a colleague.
It helps us keep this content free. |
|
|
|
./TOP_NEWS
| | xAI launches Grok 4 and its multi-agent version to boost answer quality through agent collaboration
| 190,439 Likes |
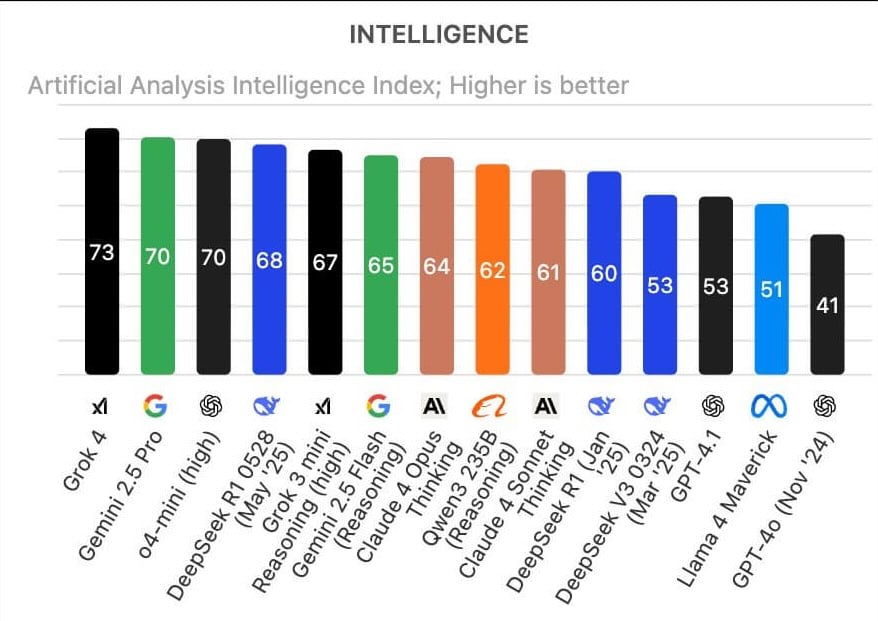
| xAI has released Grok 4, its latest flagship model, through API and premium subscription. Grok 4 claims top-tier performance in reasoning, math, and coding outperforming GPT-4, Claude, and Gemini to earn #1 across key benchmarks.
It also introduces a multi-agent variant, Grok 4 Heavy, for answer quality through agent collaboration.
How does it work at a high level? Grok 4 is a multimodal reasoning model which supports 256,000 token context. The Heavy version runs multiple agents in parallel like a “study group” to cross-check answers before replying. It's accessible via the xAI API and integrated into X.
Key Features
256K context window for complex documents and chains of thought Function calling and structured output support Reasoning-first architecture ("thinks before answering") Available via xAI API and soon on Azure API access with rate limits: 60 req/min, 16k tokens/min $3 per 1M input tokens, $15 per 1M output tokens How to use it?
Use the grok-4-0709 model through the API for applications, or interact with it directly via the Grok chatbot. Grok 4 is also being rolled out to enterprise platforms and may be hosted on Azure AI Foundry.
SuperGrok Heavy subscribers, paying $300/month, get early access to Grok 4 Heavy and upcoming features, including a coding model, a multimodal agent, and video generation.
Main Limitations Grok 4’s context window (256K) is smaller than Gemini 2.5 Pro’s 1M. It’s slower in token generation and costs more than most peers. xAI’s enterprise platform is early-stage and has limited tool integration.
Community Feedback "Grok 4 looks very strong. Importantly, it has a mode where multiple agents go do the same task in parallel, then compare their work and figure out the best answer. In the future, the amount of intelligence you get will just be based on how much compute you throw at it."
- Aaron Levie
"Almost every response I have gotten with Grok 4 has something like: "If this isn't what you wanted or you have something specific in mind, please let me know and I will assist!" This seems overly helpful and feels similar in nature to the sycophantic behaviour we saw from 4o" - wh |
|
| Try now
|
|
|
|
| Deploy NVIDIA GPU Clusters in Minutes with Lambda 1-Click Clusters™
| Get your AI workloads running in minutes, not quarters. The ESG Technical Validation report proves Lambda 1-Click Clusters simplify and speed up every step.
Provision pre-validated clusters faster versus standard clouds
Skip setup headaches, hardware isolation ensures security from day one
No hidden egress or ingress fees to inflate bills
Start with Lambda Stack pre-installed: PyTorch, TensorFlow, NVIDIA drivers
Manage compute, network, and storage with a single streamlined workflow
Download the ESG report for a detailed breakdown and see the time-to-value difference. |
| Download the report
| partner with us |
|
|
|
./TOP_SIGNALS
| |
Perplexity releases Comet, a browser with an AI assistant that automates meetings, emails, and browsing tasks
|
11,387 Likes | |
Anthropic launches free Claude courses with hands-on labs, covering API, MCP, and Claude Code workflows
|
7,384 Likes | |
Google ships asynchronous Batch Mode that accelerates model evaluations and bulk content generation using Gemini 2.5
|
2,294 Likes | |
|
Higgsfield introduces Soul ID, letting you create high-quality lookbooks that maintains consistency
|
6,294 Likes | |
Hugging Face rolls out SmolLM3, an open-source 3B model with 128k-token reasoning support
|
1,392 Likes | |
ZeroRank releases Zerank-1, an open-source SOTA reranker that improves retrieval accuracy, outperforms Cohere
|
302 Likes
| | |
|
|
|
|
Replit has a new AI Project Gallery to discover and clone apps
| On the Joe Rogan show, Replit user Ahmad George shared how he built a custom ERP in Replit for $400. His company had been quoted $150K for the same software.
He sold it back to his employer for $32K.
|
Try Replit now ↗️ |
|
|
|
./TOP_TUTORIALS
| |
| 2,749 Likes |
Learn how to use Claude Code to automate dev tasks in 36 minutes. This 10-lesson guide covers GitHub automation, custom workflows, and MCP integration.
| |
|
| 1,138 Likes |
This tutorial shows how to integrate long-term memory into a Gemini 2.5 chatbot using Mem0. You’ll build an assistant that uses embedding models while integrating with Gemini API to build an assistant that remembers user history for persistent conversations across sessions.
|
|
|
| 1,049 Likes |
You will learn how to serve any Python function as an MCP tool using gradio[mcp]. Using this tutorial, you can expose endpoints, auto-generate schemas, and support LLM integration with one line of code.
|
| |
| |
|
|
./PYTHON_TIP
| | Trace and Debug LLM Pipelines with a Decorator
|
Component-level tracing helps debug LLM pipelines more effectively. Instead of treating your app as a black box, use @observe decorator from the open-source deepeval package.
What it does?
It monitors specific parts of your LLM pipeline, like retrievers or tools, without modifying existing logic. The function uses targeted metrics to help you identify performance of different components
When and How to use it?
Each @observe adds tracing to a specific part of your app. You can attach evaluation metrics and get visual breakdowns of performance across components.
This is especially useful for RAG systems and agent workflows where failures can be subtle and localized. |
from deepeval.tracing import observe

@observe(name="Retriever")
def retrieve(query):
    return vector_db.search(query)

@observe(name="Generator")
def generate(context):
    return llm.generate(context)
| | Github repo |
|
|
|
At Alpha Signal, our mission is to build a sharp, engaged community focused on AI, machine learning, and cutting-edge language models, helping over 200,000 developers stay informed and ahead. We’re passionate about curating the best in AI, from top research and trending technical blogs to expert insights and tailored job opportunities. We keep you connected to the breakthroughs and discussions that matter, so you can stay in the loop without endless searching. We also work closely with partners who value the future of AI, including employers and advertisers who want to reach an audience as passionate about AI as we are.
Our partnerships are based on shared values of ethics, responsibility, and a commitment to building a better world through technology.Privacy is a priority at Alpha Signal. Our Privacy Policy clearly explains how we collect, store, and use your personal and non-personal information. By using our website, you accept these terms, which you can review on our website. This policy applies across all Alpha Signal pages, outlining your rights and how to contact us if you want to adjust the use of your information. We’re based in the United States. By using our site, you agree to be governed by U.S. laws. |
|
|
|
Looking to promote your company, product, service, or event to 200,000+ AI developers? Let's work together.
|
| Work with us
|
|
|
|
|
