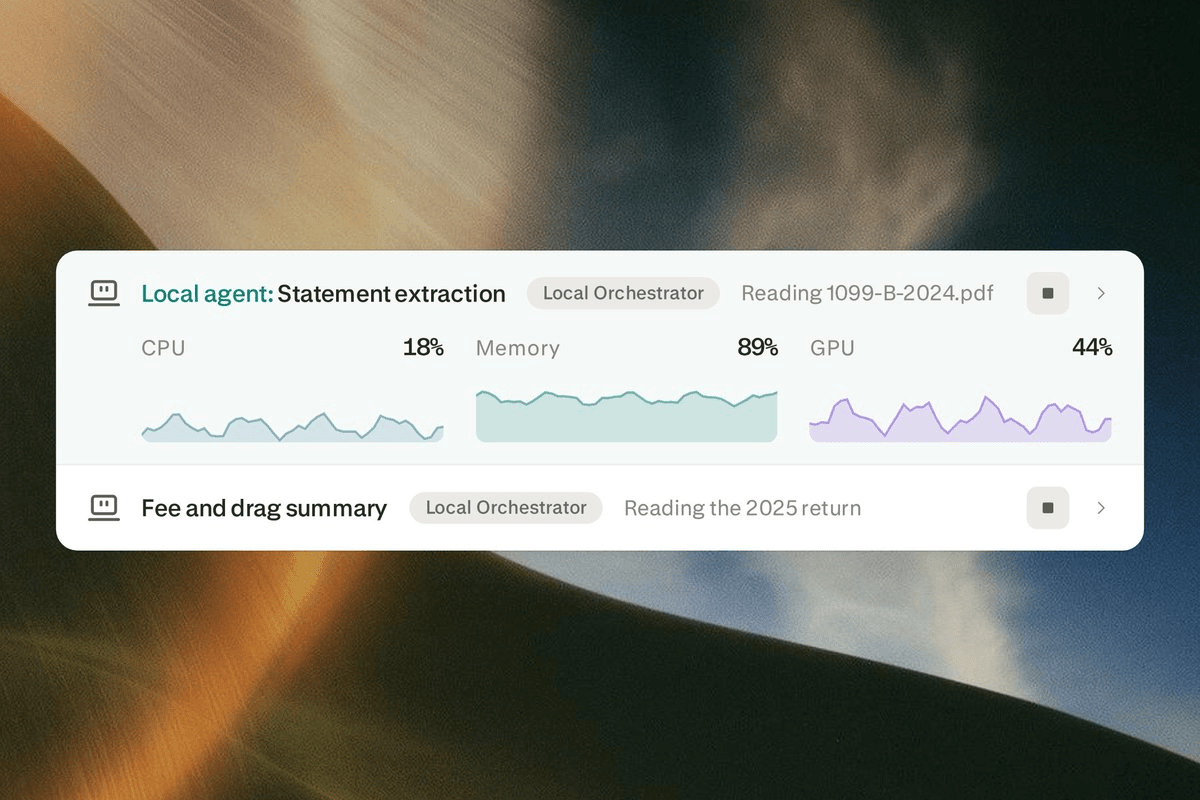
Perplexity's new Portable Computer runs the full agent stack locally on NVIDIA DGX Spark, with cloud escalation gated by user approval and zero per-token cost for on-device work.
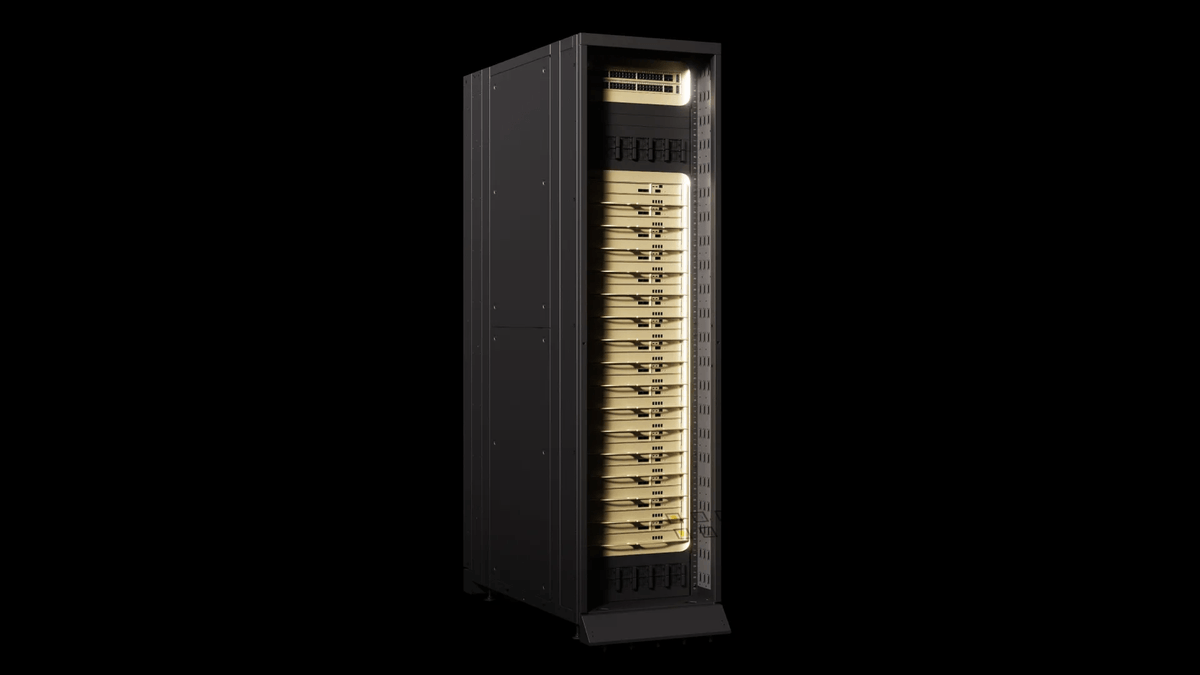
NVIDIA's new inference accelerator hit 3,431 tokens/second on Gemma 4 31B at 100K context, roughly 4x the fastest public endpoint in third-party testing.
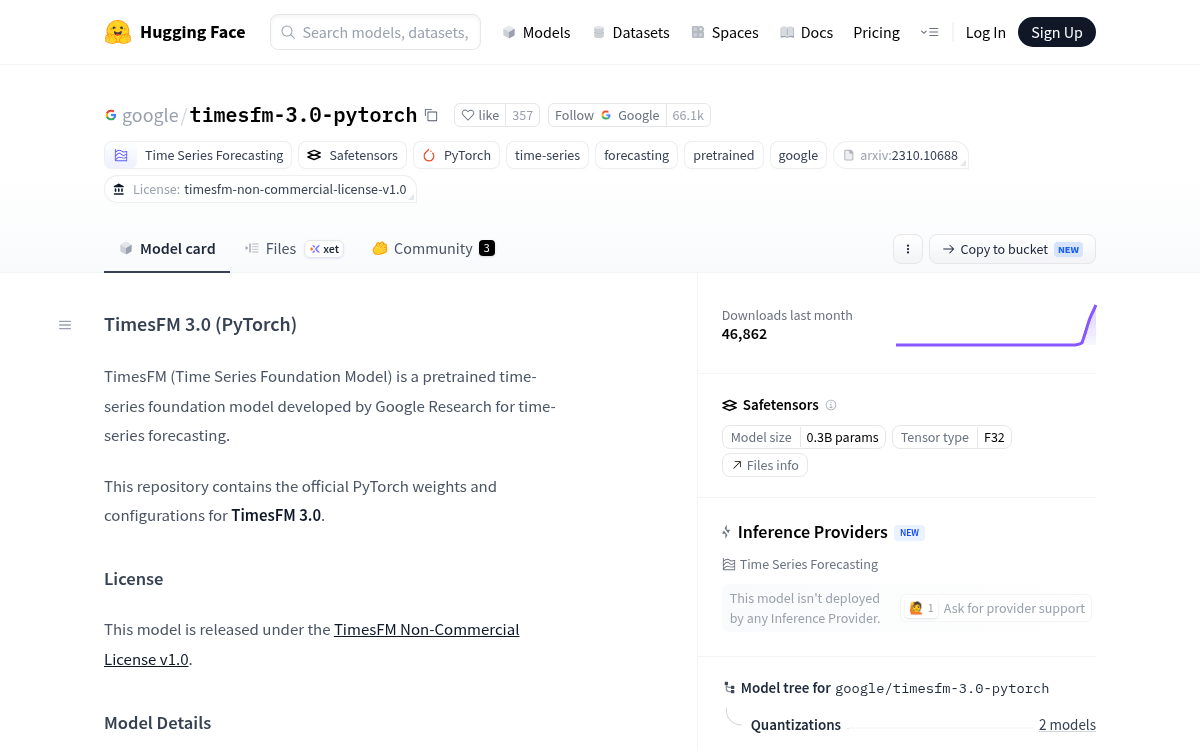
Google Research drops a 330M-parameter foundation model that forecasts multiple related time series jointly, topping three zero-shot benchmarks but locked to non-commercial use.
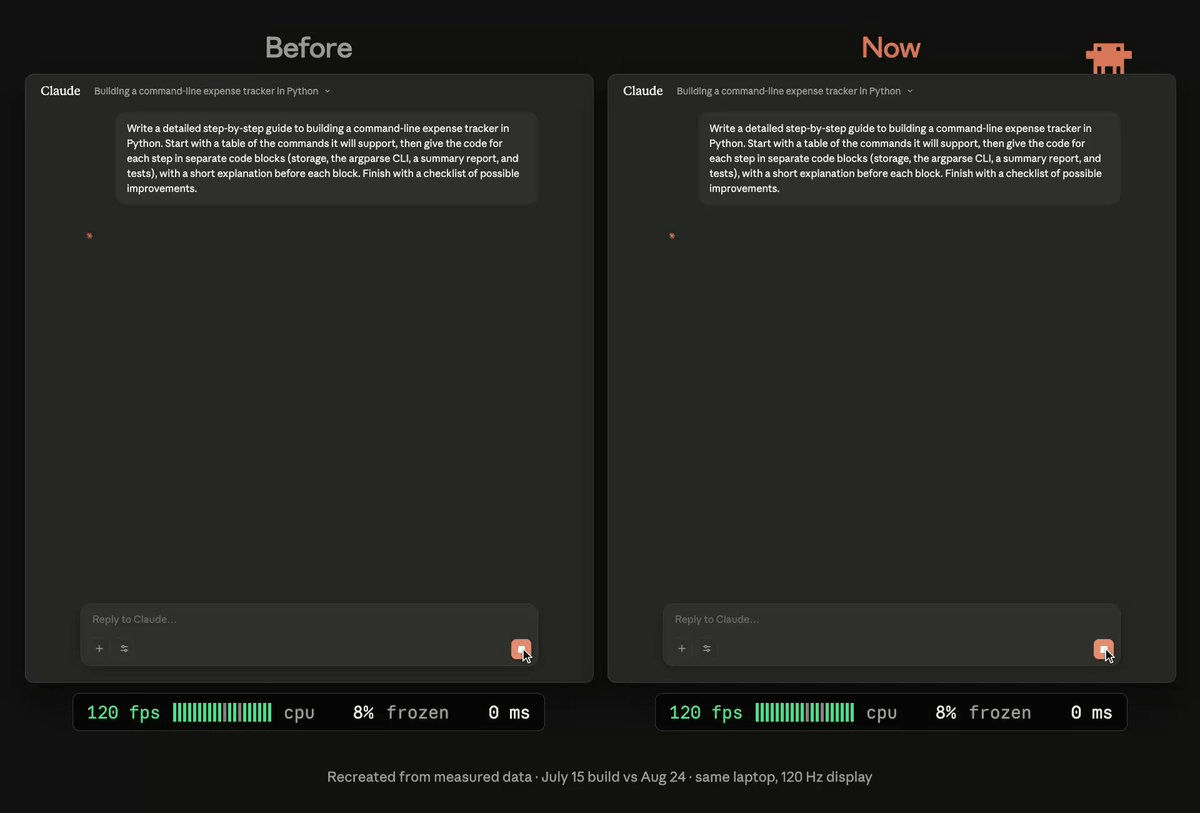
Anthropic rebuilt the Claude web and desktop streaming renderer to only update changing text, cutting stalls by 9x and holding 120fps on ProMotion Macs.
Thinking Machines Lab is offering up to $50,000 in Tinker credits to researchers tackling the hardest open-weight model safety problems, from tamper-resistant safeguards to worst-case risk forecasting.
Mistral is trading solo AI ambitions for Gulf compute, joining Saudi's HUMAIN in a hundreds-of-millions-of-euros push into sovereign, Arabic-first models.
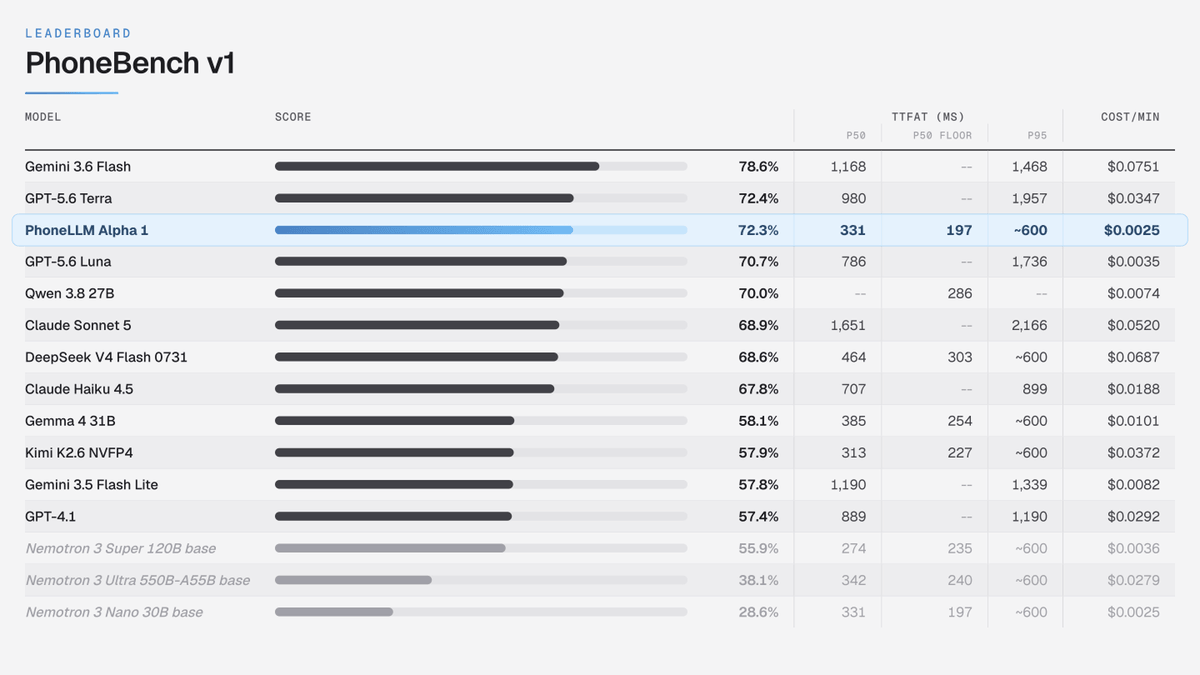
Mia-AiLab shipped a 5.0bpw EXL3 quant of the DFlash2 speculative drafter for Qwen3.8-27B, cutting draft weight from 3.85 GB to 1.4 GB and lifting decode throughput 33 percent on DGX Spark.
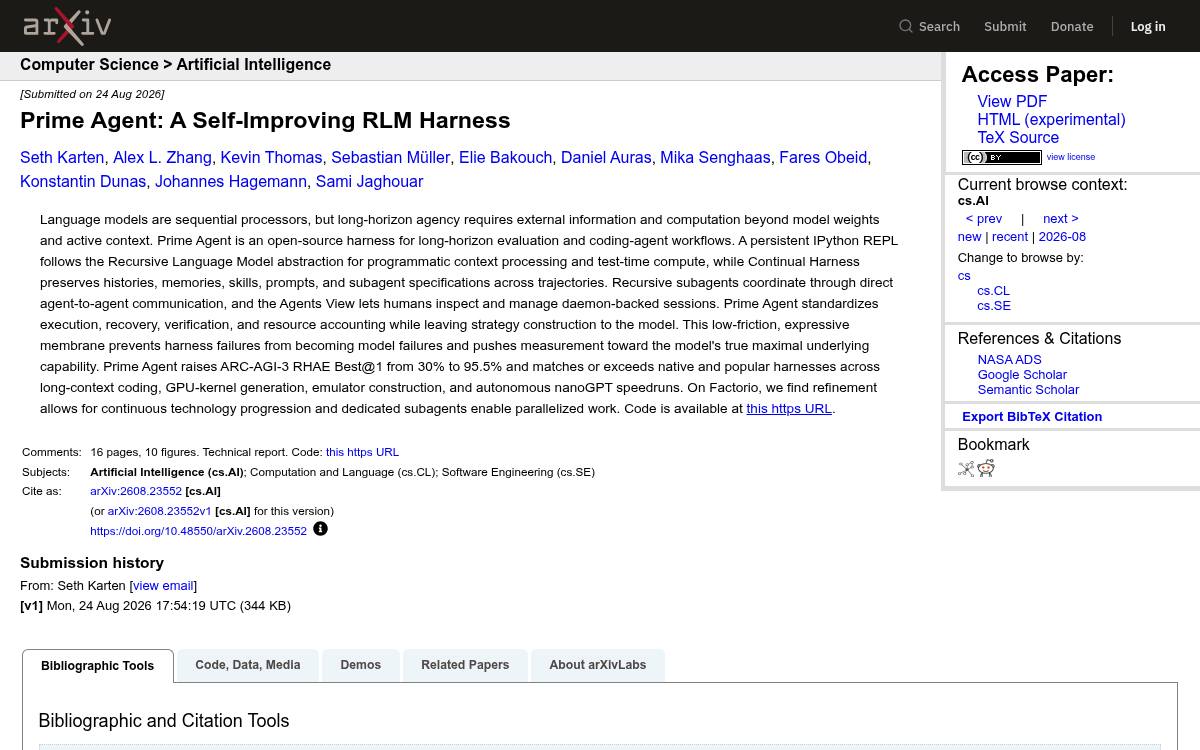
Prime Intellect's open-source harness turns agents into programmable systems, driving ARC-AGI-3 scores from 30% to 95.5% and enabling week-long autonomous runs.

 Pro
 Pro
 Pro
 Pro
 Pro
 Pro
 Pro